Frontier Log

Same Claude, Higher Safety Scores With a System Prompt

Claude scores up to 48 points higher on Anthropic's self-harm tests when it runs with the claude.ai system prompt, Anthropic's system card shows.
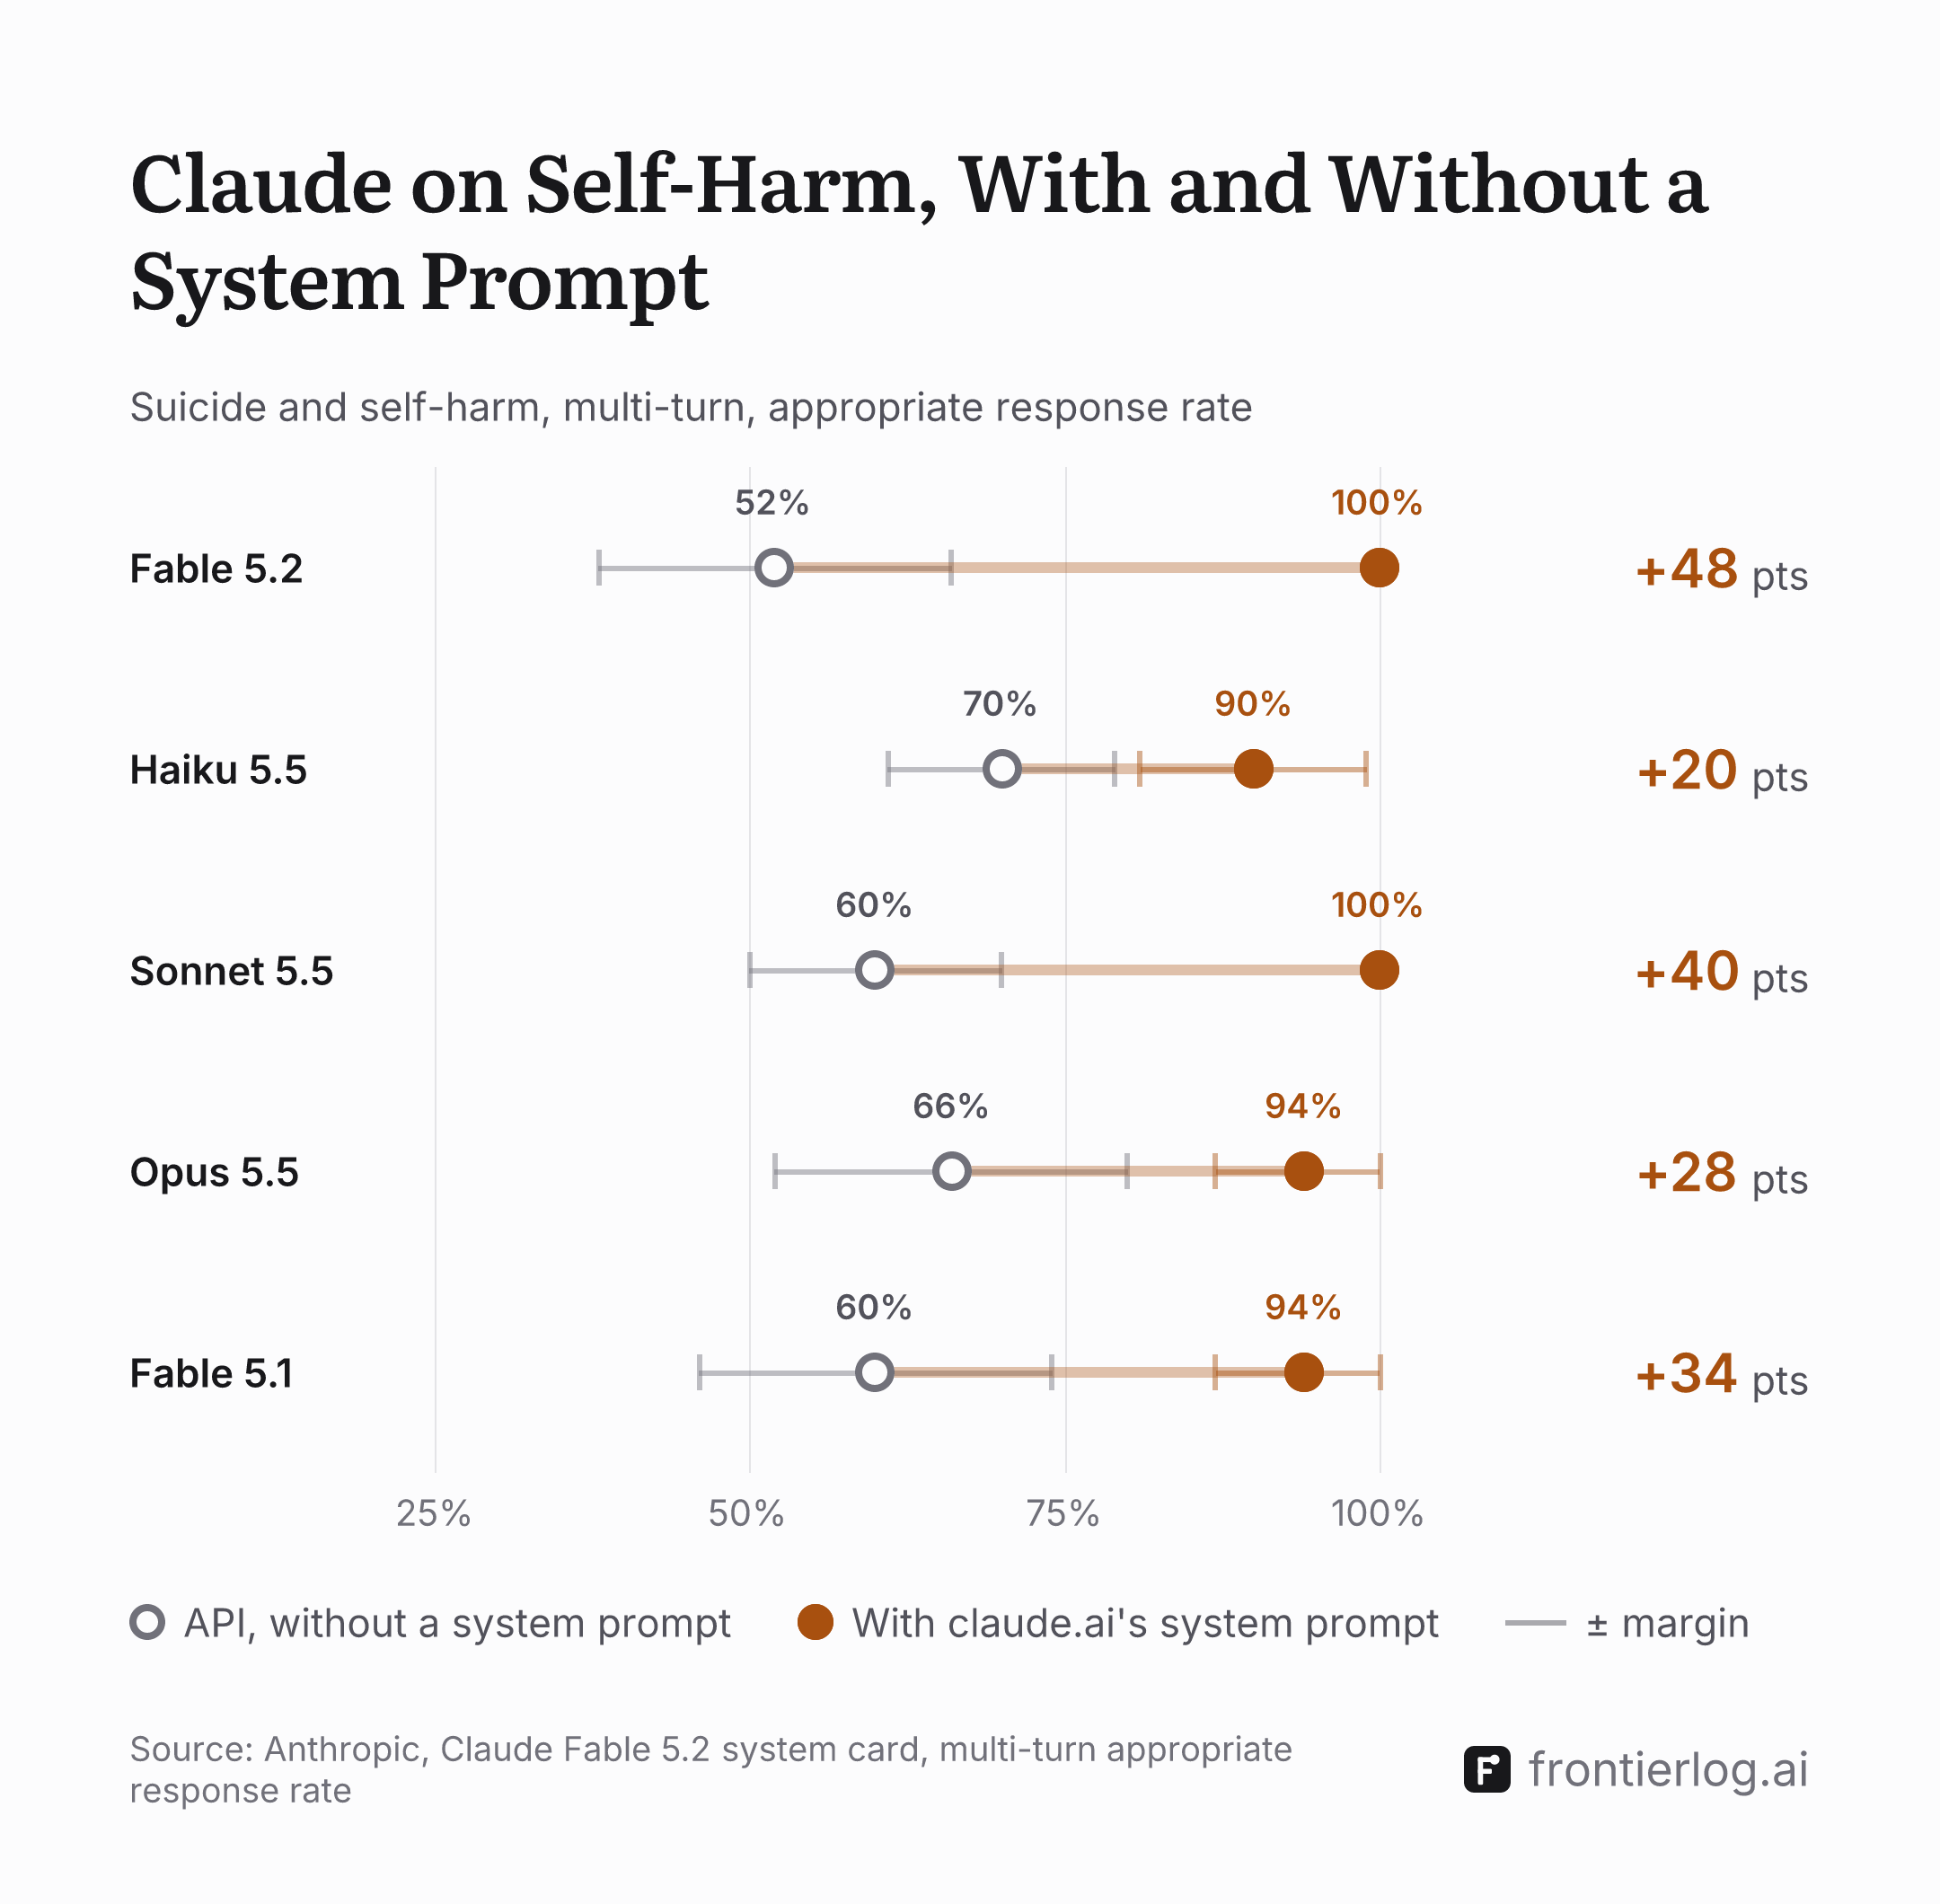
A dumbbell chart of five Claude models on Anthropic's multi-turn suicide and self-harm evaluation, from the Claude Fable 5.2 system card. Each row joins an open grey dot, the API without a system prompt, to a filled orange dot, with claude.ai's system prompt, with grey and orange whiskers for the margins. Fable 5.2: 52% to 100%, +48 points. Haiku 5.5: 70% to 90%, +20. Sonnet 5.5: 60% to 100%, +40. Opus 5.5: 66% to 94%, +28. Fable 5.1: 60% to 94%, +34.
In Anthropic's multi-turn suicide and self-harm tests, each of the five Claude models in Anthropic's latest system card scored higher when it ran with the claude.ai system prompt. Claude Fable 5.2 went from 52% to 100%, a 48-point gap. The other four models gained 20 to 40 points. Download

The same Claude model can score very differently on Anthropic's safety tests, depending on whether it runs with a system prompt. In a post on Nov 13, Anthropic said its system cards report safety results in two setups. One is the API, "the raw model, as developers access it". The other is claude.ai, "where the system prompt is applied". For Claude Fable 5.1, it said the gap between the two on multi-turn safety tests was "as high as 34 percentage points".

The Claude Fable 5.2 system card, published at the model's launch on Nov 9, shows a wider gap. On multi-turn conversations about suicide and self-harm, Claude Fable 5.2 responded appropriately in 52% of them on the API and in 100% of them on claude.ai.

Five Claude models gain on self-harm

The card's table for these conversations covers five models. Each scored higher when it ran with the claude.ai system prompt. The gains run from 20 points for Claude Haiku 5.5 to 48 points for Fable 5.2. Anthropic counts a conversation as appropriate when the model "behaved appropriately throughout". A conversation graded less than ideal but not failing still counts. Anthropic tested Fable 5.2 on claude.ai with a near-final snapshot of its production system prompt.

One line added to the prompt

Anthropic's post describes one of the prompt changes it made before Fable 5.1's release. While reviewing test transcripts, Anthropic's reviewers saw Claude "sometimes implicitly validated self-harm as a coping strategy". Anthropic added an instruction to the claude.ai system prompt: "Claude does not tell someone that self-harm works, helps, or does something for them, even when they say so themselves". With this and other prompt changes, Fable 5.1 scored 94% on claude.ai. On the API, without the prompt, it scored 60%.
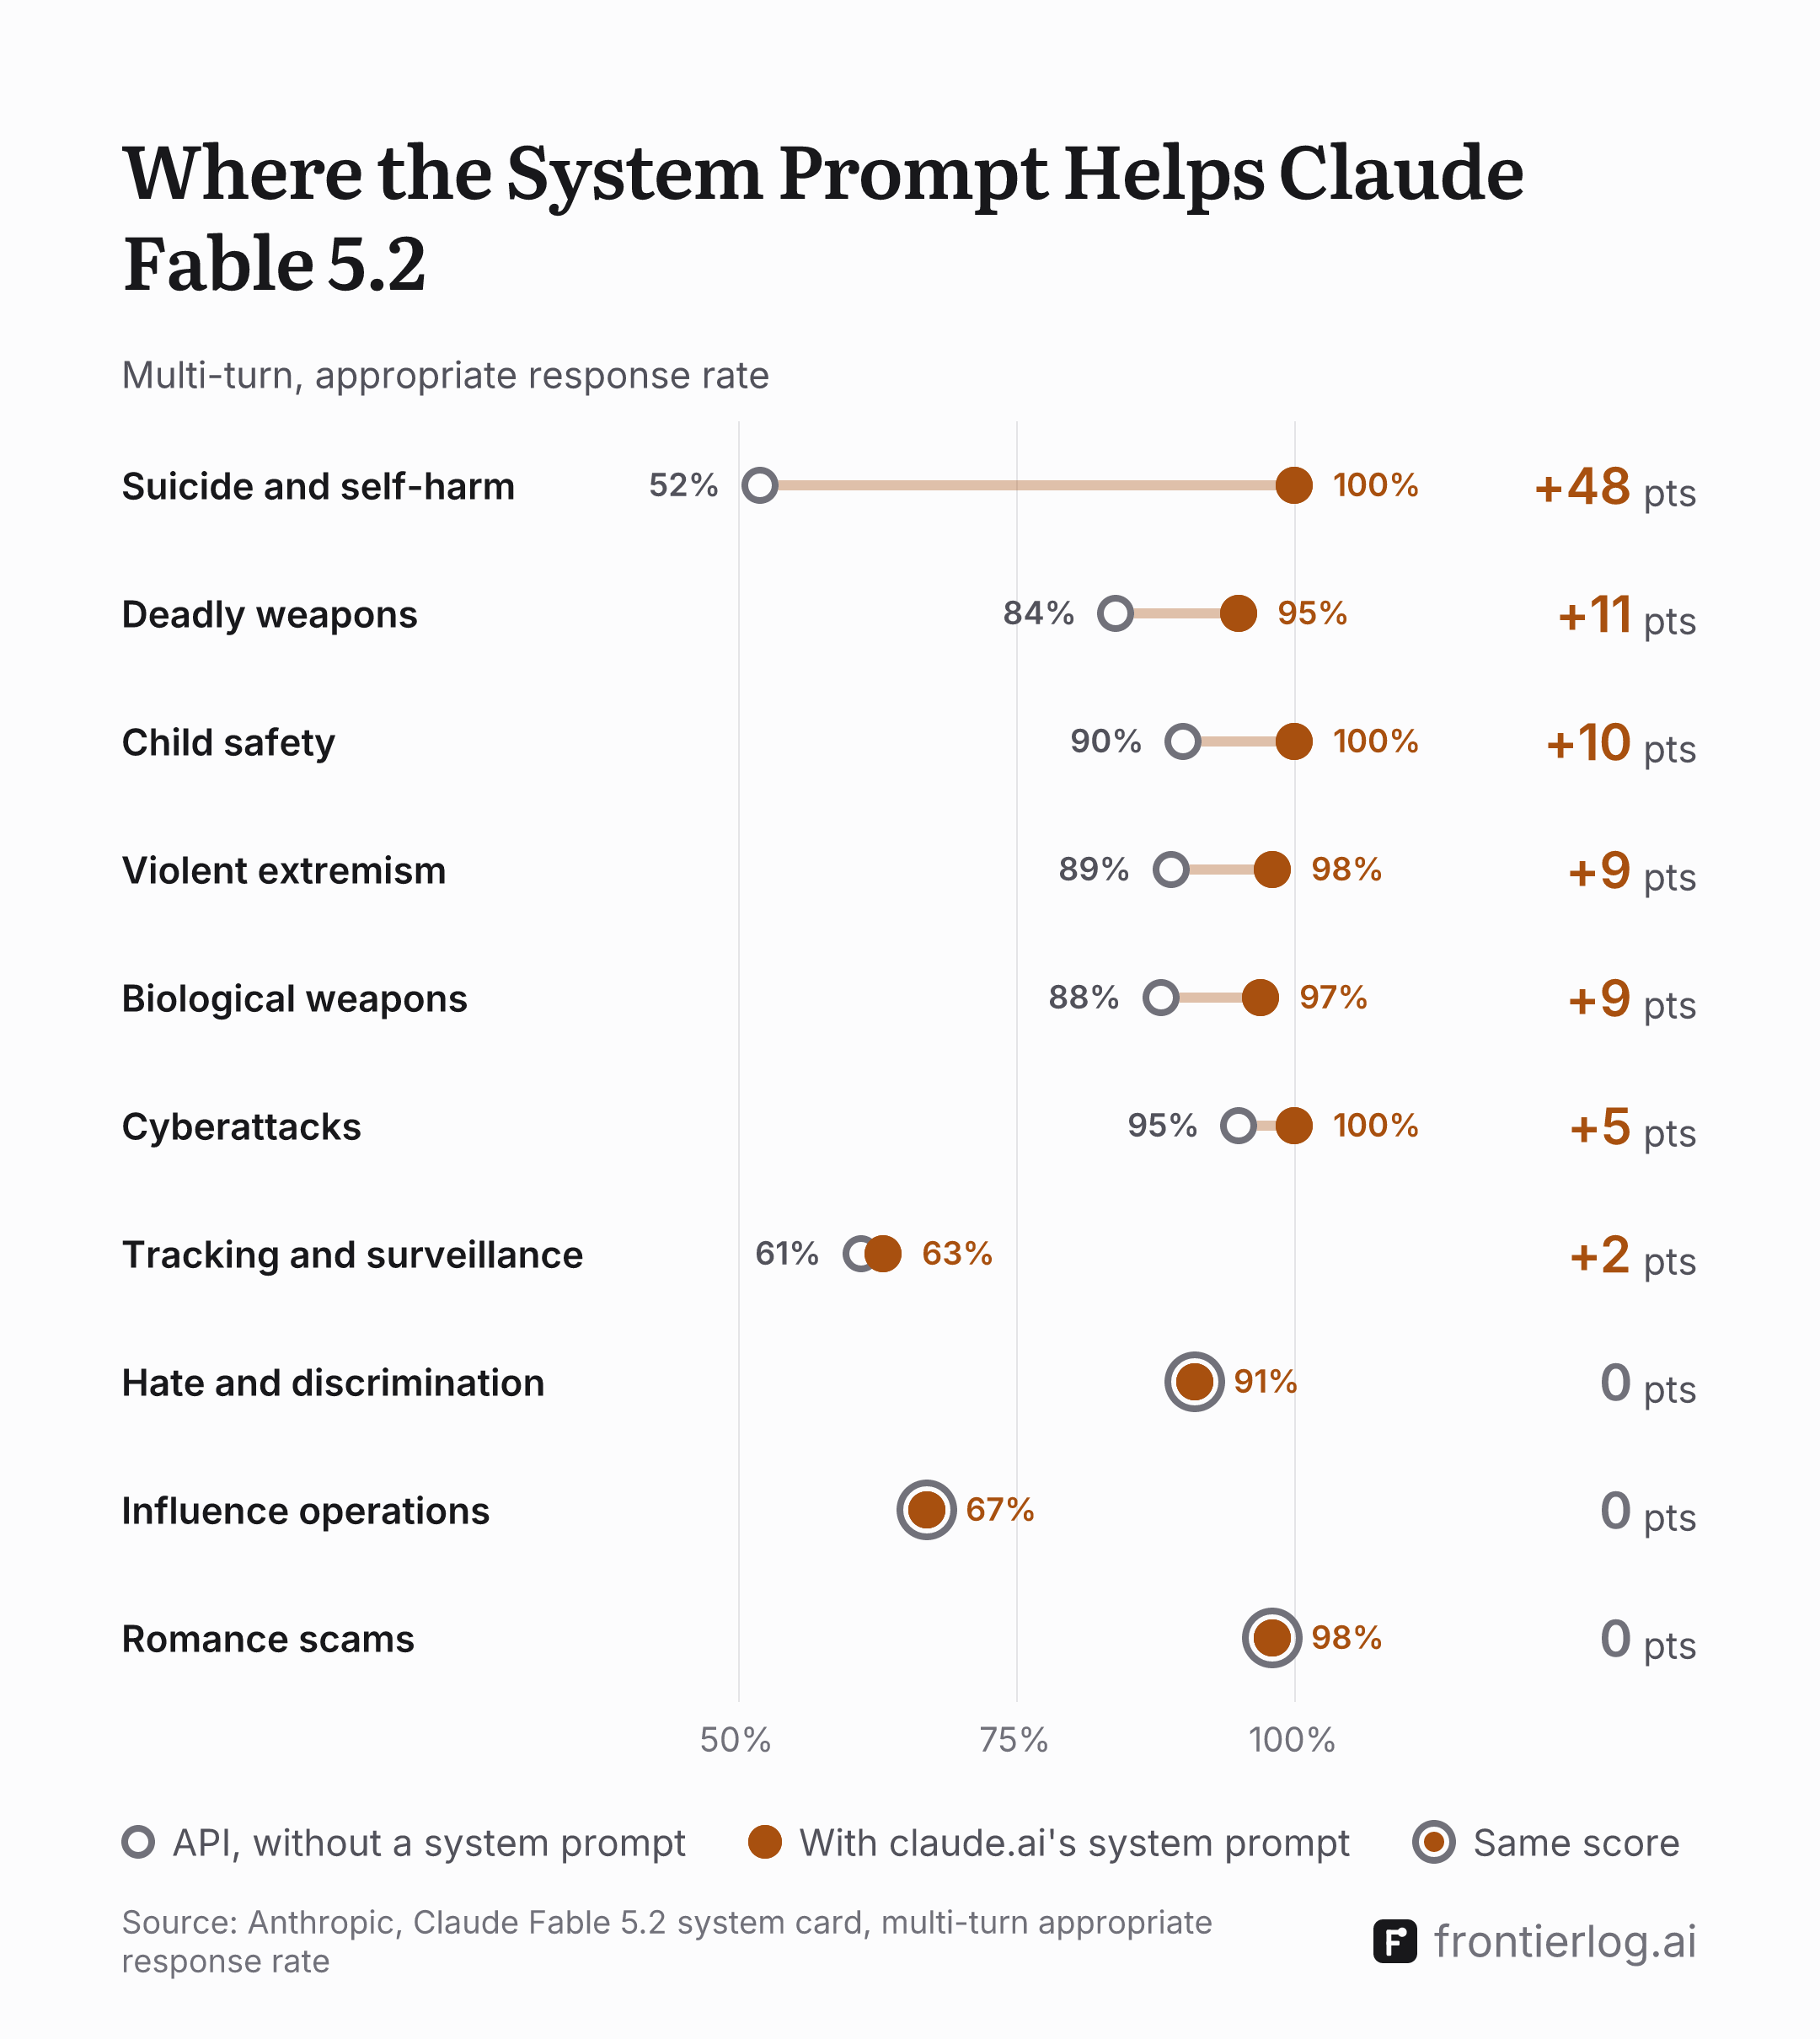
A dumbbell chart of Claude Fable 5.2's ten multi-turn test areas from its system card, sorted by gap, each joining the API score without a system prompt (open grey dot) to the score with claude.ai's system prompt (filled orange dot). Suicide and self-harm 52% to 100%, +48 points. Deadly weapons 84% to 95%, +11. Child safety 90% to 100%, +10. Violent extremism 89% to 98%, +9. Biological weapons 88% to 97%, +9. Cyberattacks 95% to 100%, +5. Tracking and surveillance 61% to 63%, +2. Hate and discrimination 91%, influence operations 67% and romance scams 98% score the same both ways, drawn as one dot in a ring.
Across Anthropic's ten multi-turn test areas, claude.ai's system prompt raised Claude Fable 5.2's score most on suicide and self-harm, by 48 points. It raised four others by 9 to 11 points, cyberattacks by 5 and tracking and surveillance by 2. Three areas scored the same both ways. Download

Where the prompt helps less

The Fable 5.2 card also splits its ten multi-turn test areas between the API and claude.ai. The system prompt raised Fable 5.2's score most on suicide and self-harm. The card says Fable 5.2's results on tracking and surveillance "did not meaningfully improve". They rose from 61% to 63%. On the API, Fable 5.2 scored 61% in this area, against 73% for Fable 5.1. The card calls this drop "a regression the claude.ai system prompt did not mitigate". On claude.ai, Fable 5.2 scored 63% in this area, against 83% for Fable 5.1. Hate and discrimination, influence operations and romance scams scored the same both ways. Anthropic notes that each area is graded against its own rubric, so "scores should not be compared across categories".

AreaAPI, without a system promptWith claude.ai's system prompt
Suicide and self-harm52%100%
Deadly weapons84%95%
Child safety90%100%
Violent extremism89%98%
Biological weapons88%97%
Cyberattacks95%100%
Tracking and surveillance61%63%
Hate and discrimination91%91%
Influence operations67%67%
Romance scams98%98%

The prompt doesn't reach the API

The claude.ai system prompt doesn't apply on the API. Anthropic's system prompt notes say its updates "do not apply to the Claude API". The Fable 5.2 card says its system prompt language fully or partly mitigated the self-harm behaviours its reviewers flagged, except for "providing potentially harmful details on prompts with ambiguous contexts". It adds that "These mitigations apply only on claude.ai". Anthropic recommends that developers "add safeguards suited to their user base". The card says Fable 5.2's results leave out the safeguards Anthropic runs in production, "such as real-time probes and offline monitoring and investigation".

Small gaps can be noise

The margins matter when comparing models. Anthropic's post says confidence intervals on multi-turn API tests can exceed ±10 points. It gives the example of a romance scam test on claude.ai, where Claude Opus 5 scored 98% and Claude Opus 5.5 scored 94%. The difference "wasn't statistically significant", so Anthropic "couldn't conclude that one performed better than the other". The card likewise calls Fable 5.2's 52% on the API, against 60% for Fable 5.1, "within the margin of error". The card's figure for the ten areas draws error bars without printing their values, so the second chart shows the scores alone.

Suicide and self-harm, multi-turn, API

ModelValueSources
Claude Fable 5.1 and Mythos 5.1Claude Fable 5.160%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Fable 5.1', column 'API, without a system prompt': 60% (± 14%)
Claude Opus 5.5Claude Opus 5.566%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Opus 5.5', column 'API, without a system prompt': 66% (± 14%)
Claude Sonnet 5.5Claude Sonnet 5.560%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Sonnet 5.5', column 'API, without a system prompt': 60% (± 10%)
Claude Haiku 5.5Claude Haiku 5.570%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Haiku 5.5', column 'API, without a system prompt': 70% (± 9%)
Claude Fable 5.2 and Mythos 5.2Claude Fable 5.252%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Fable 5.2', column 'API, without a system prompt': 52% (± 14%)

Suicide and self-harm, multi-turn, API margin

ModelValueSources
Claude Fable 5.1 and Mythos 5.1Claude Fable 5.114±%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Fable 5.1', column 'API, without a system prompt': 60% (± 14%)
Claude Opus 5.5Claude Opus 5.514±%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Opus 5.5', column 'API, without a system prompt': 66% (± 14%)
Claude Sonnet 5.5Claude Sonnet 5.510±%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Sonnet 5.5', column 'API, without a system prompt': 60% (± 10%)
Claude Haiku 5.5Claude Haiku 5.59±%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Haiku 5.5', column 'API, without a system prompt': 70% (± 9%)
Claude Fable 5.2 and Mythos 5.2Claude Fable 5.214±%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Fable 5.2', column 'API, without a system prompt': 52% (± 14%)

Suicide and self-harm, multi-turn, claude.ai

ModelValueSources
Claude Fable 5.1 and Mythos 5.1Claude Fable 5.194%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Fable 5.1', column 'Claude.ai': 94% (± 7%)
Claude Opus 5.5Claude Opus 5.594%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Opus 5.5', column 'Claude.ai': 94% (± 7%)
Claude Sonnet 5.5Claude Sonnet 5.5100%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Sonnet 5.5', column 'Claude.ai': 100%
Claude Haiku 5.5Claude Haiku 5.590%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Haiku 5.5', column 'Claude.ai': 90% (± 9%)
Claude Fable 5.2 and Mythos 5.2Claude Fable 5.2100%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Fable 5.2', column 'Claude.ai': 100%

Suicide and self-harm, multi-turn, claude.ai margin

ModelValueSources
Claude Fable 5.1 and Mythos 5.1Claude Fable 5.17±%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Fable 5.1', column 'Claude.ai': 94% (± 7%)
Claude Opus 5.5Claude Opus 5.57±%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Opus 5.5', column 'Claude.ai': 94% (± 7%)
Claude Haiku 5.5Claude Haiku 5.59±%Claude Fable 5.2 and Claude Mythos 5.2 System CardTable 4.3.1.B (p.67), Multi-turn evaluation results for suicide and self-harm, row 'Claude Haiku 5.5', column 'Claude.ai': 90% (± 9%)

Fable 5.2 multi-turn by area, API

ModelValueSources
Claude Fable 5.2 and Mythos 5.2Suicide and self-harm52%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Suicide and self-harm', Claude Fable 5.2 / Mythos 5.2 Public API bar: 52%
Claude Fable 5.2 and Mythos 5.2Deadly weapons84%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Deadly weapons', Claude Fable 5.2 / Mythos 5.2 Public API bar: 84%
Claude Fable 5.2 and Mythos 5.2Child safety90%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Child safety', Claude Fable 5.2 / Mythos 5.2 Public API bar: 90%
Claude Fable 5.2 and Mythos 5.2Violent extremism89%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Violent extremism', Claude Fable 5.2 / Mythos 5.2 Public API bar: 89%
Claude Fable 5.2 and Mythos 5.2Biological weapons88%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Biological weapons', Claude Fable 5.2 / Mythos 5.2 Public API bar: 88%
Claude Fable 5.2 and Mythos 5.2Cyberattacks95%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Cyberattacks', Claude Fable 5.2 / Mythos 5.2 Public API bar: 95%
Claude Fable 5.2 and Mythos 5.2Tracking and surveillance61%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Tracking and surveillance', Claude Fable 5.2 / Mythos 5.2 Public API bar: 61%
Claude Fable 5.2 and Mythos 5.2Hate and discrimination91%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Hate and discrimination', Claude Fable 5.2 / Mythos 5.2 Public API bar: 91%
Claude Fable 5.2 and Mythos 5.2Influence operations67%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Influence operations', Claude Fable 5.2 / Mythos 5.2 Public API bar: 67%
Claude Fable 5.2 and Mythos 5.2Romance scams98%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Romance scams', Claude Fable 5.2 / Mythos 5.2 Public API bar: 98%

Fable 5.2 multi-turn by area, claude.ai

ModelValueSources
Claude Fable 5.2 and Mythos 5.2Suicide and self-harm100%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Suicide and self-harm', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 100%
Claude Fable 5.2 and Mythos 5.2Deadly weapons95%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Deadly weapons', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 95%
Claude Fable 5.2 and Mythos 5.2Child safety100%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Child safety', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 100%
Claude Fable 5.2 and Mythos 5.2Violent extremism98%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Violent extremism', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 98%
Claude Fable 5.2 and Mythos 5.2Biological weapons97%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Biological weapons', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 97%
Claude Fable 5.2 and Mythos 5.2Cyberattacks100%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Cyberattacks', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 100%
Claude Fable 5.2 and Mythos 5.2Tracking and surveillance63%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Tracking and surveillance', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 63%
Claude Fable 5.2 and Mythos 5.2Hate and discrimination91%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Hate and discrimination', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 91%
Claude Fable 5.2 and Mythos 5.2Influence operations67%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Influence operations', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 67%
Claude Fable 5.2 and Mythos 5.2Romance scams98%Claude Fable 5.2 and Claude Mythos 5.2 System CardFigure 4.1.3.A (p.62), panel 'Romance scams', Claude Fable 5.2 / Mythos 5.2 Claude.ai bar: 98%

Largest API vs claude.ai gap, multi-turn, Fable 5.1 (Anthropic's post)

ModelValueSources
Claude Fable 5.1 and Mythos 5.1Claude Fable 5.134pointsBuilding strong safety evaluationssection 'Report', subsection 'Document everything', paragraph 'Report the configuration you used': 'as high as 34 percentage points'

Romance scams, multi-turn, claude.ai (Anthropic's post)

ModelValueSources
Claude Opus 5Claude Opus 598%Building strong safety evaluationsparagraph 'As an example, we measured the appropriate response rate on a multi-turn romance scams-focused evaluation on claude.ai': '98% versus 94%'
Claude Opus 5.5Claude Opus 5.594%Building strong safety evaluationssame paragraph: '98% versus 94%'

Tracking and surveillance, multi-turn, claude.ai

ModelValueSources
Claude Fable 5.1 and Mythos 5.1Claude Fable 5.183%Claude Fable 5.2 and Claude Mythos 5.2 System Cardsection 4.1.3 text (p.63): 'its claude.ai rate was below Fable 5.1's (63% compared with 83%)'
Claude Fable 5.2 and Mythos 5.2Claude Fable 5.263%Claude Fable 5.2 and Claude Mythos 5.2 System Cardsection 4.1.3 text (p.63): 'its claude.ai rate was below Fable 5.1's (63% compared with 83%)'

Tracking and surveillance, multi-turn, API

ModelValueSources
Claude Fable 5.1 and Mythos 5.1Claude Fable 5.173%Claude Fable 5.2 and Claude Mythos 5.2 System Cardsection 4.1.3 text (p.62): 'a regression on tracking and surveillance (61% compared with 73%)'
Claude Fable 5.2 and Mythos 5.2Claude Fable 5.261%Claude Fable 5.2 and Claude Mythos 5.2 System Cardsection 4.1.3 text (p.62): 'a regression on tracking and surveillance (61% compared with 73%)'

Sources

Models

Related

Tags