Frontier Log

Claude Sonnet 5.5 vs Gemini 4 Hydrogen

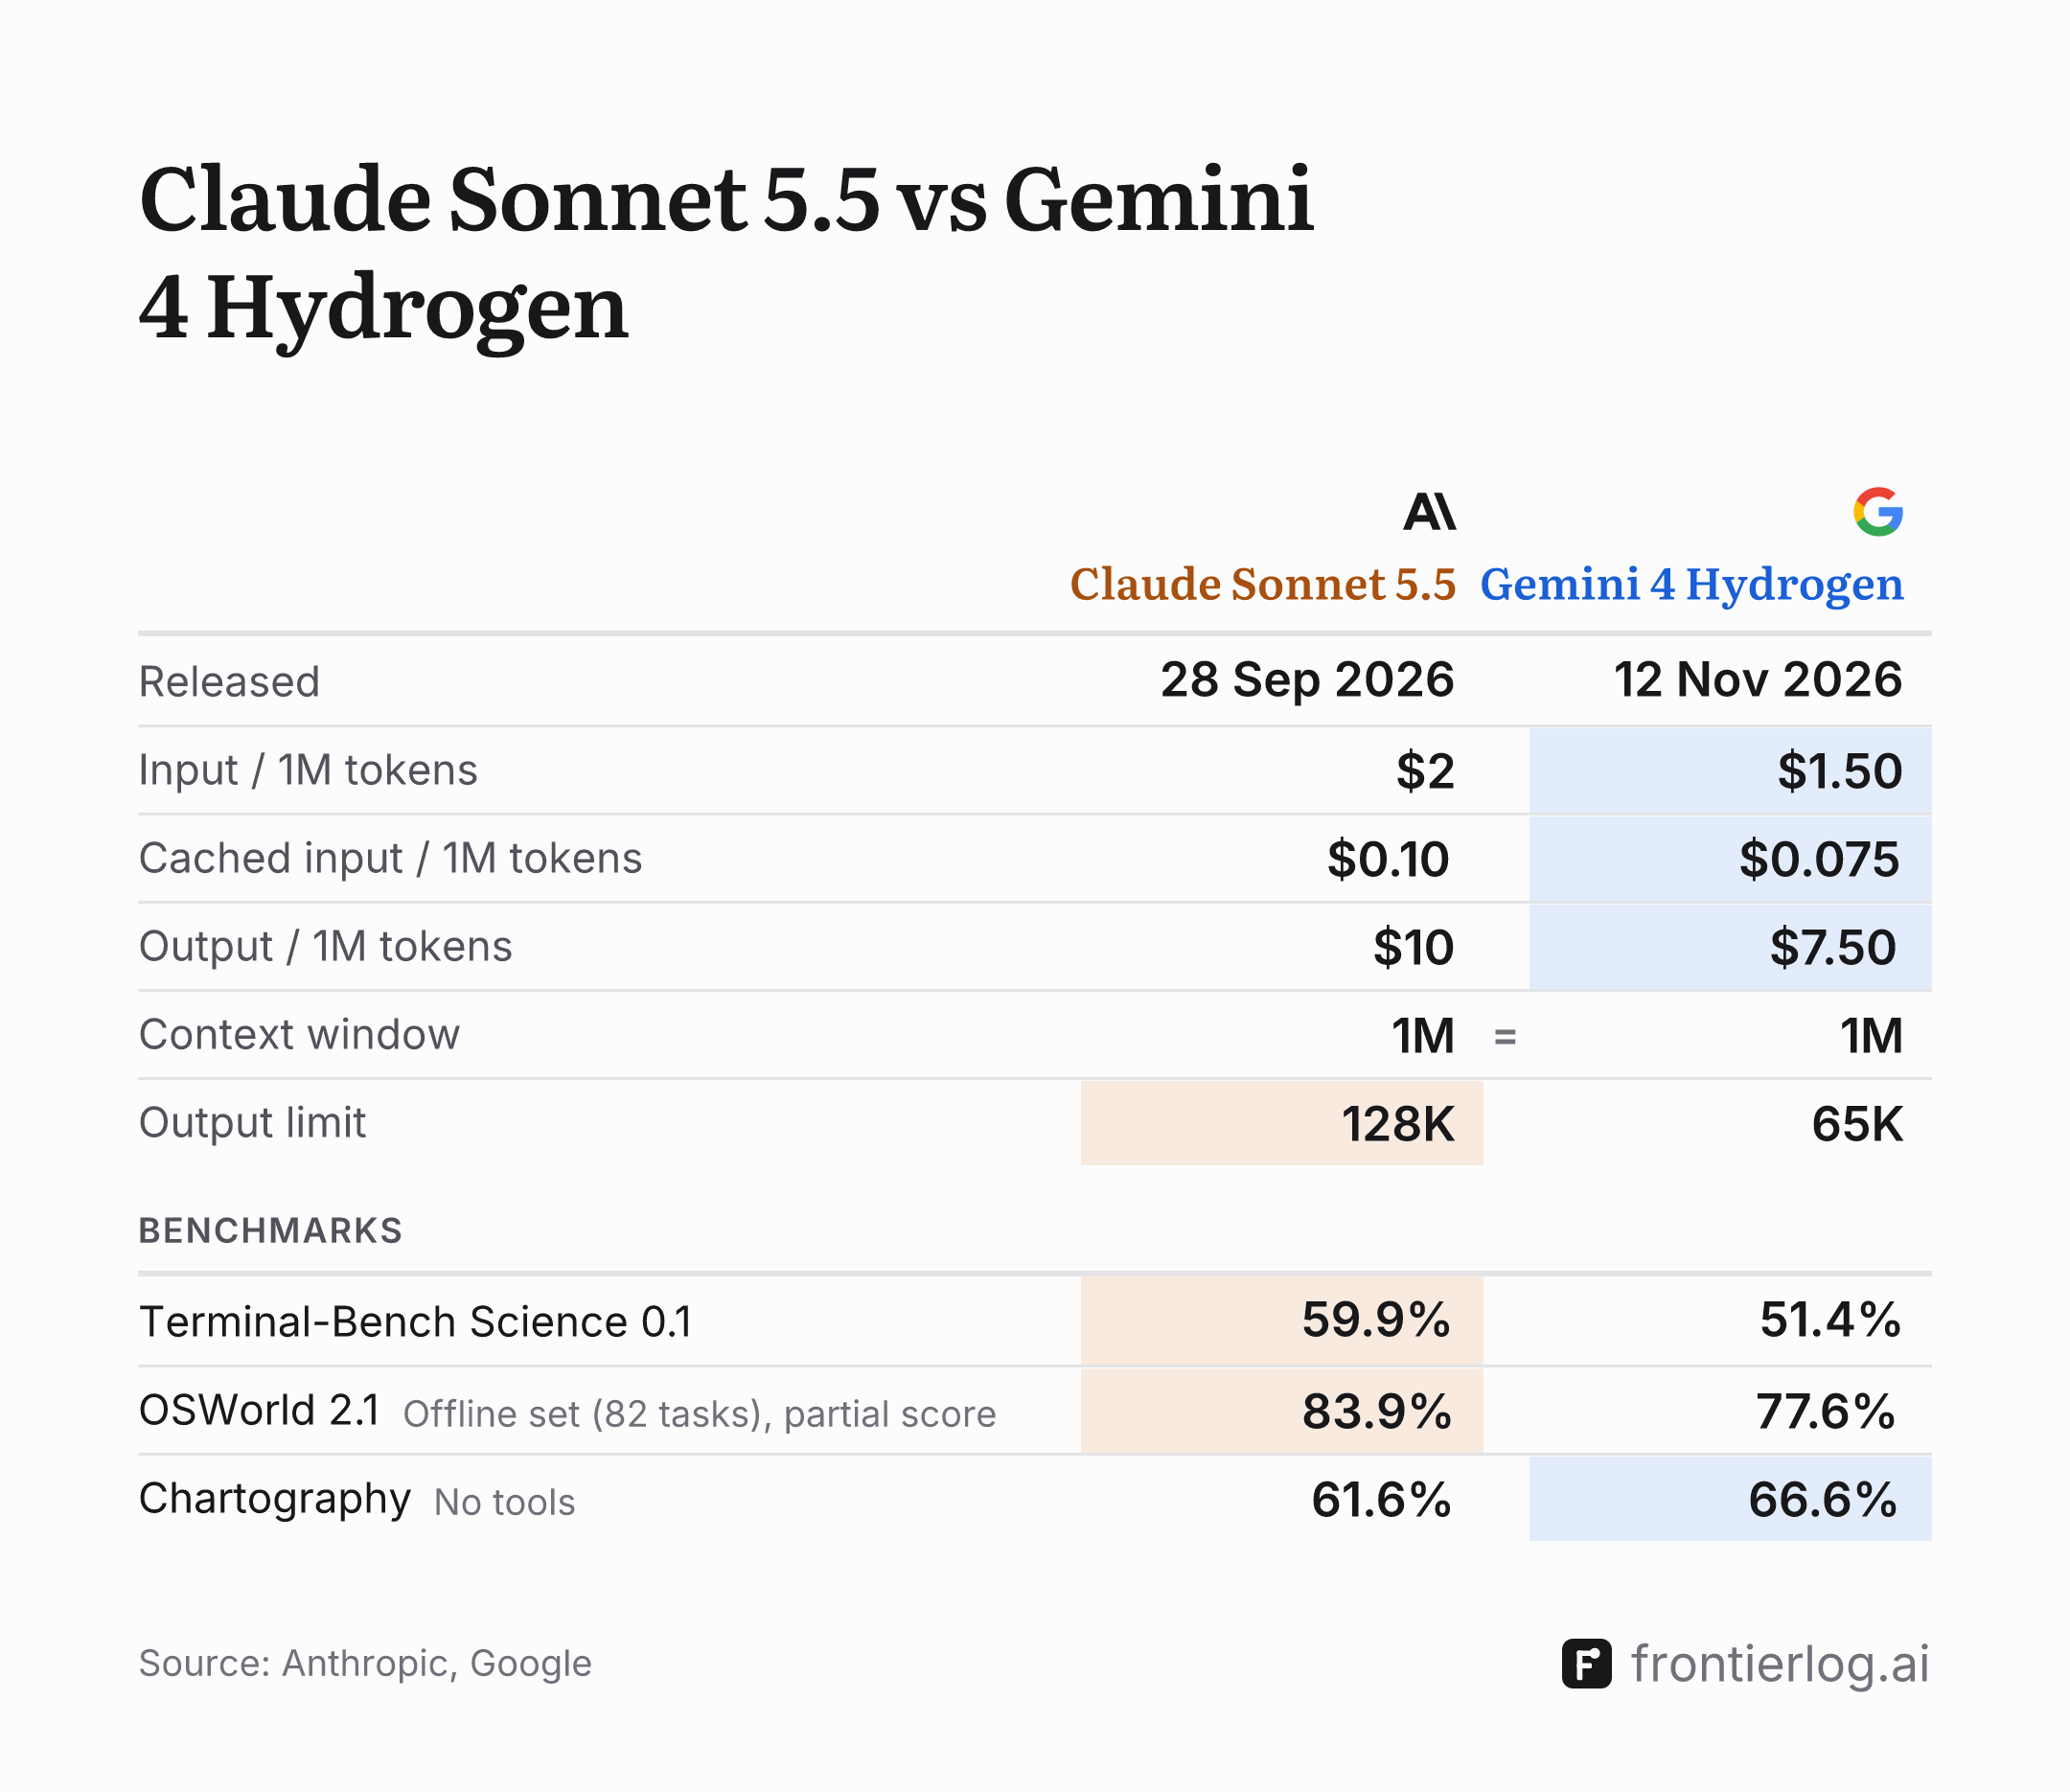
Claude Sonnet 5.5Gemini 4 Hydrogen
Released
Input / 1M tokens$2$1.50
Cached input / 1M tokens$0.10$0.075
Output / 1M tokens$10$7.50
Context window1M1M
Output limit128K65K
Benchmarks
Terminal-Bench Science 0.159.9%151.4%2
OSWorld 2.1 Offline set (82 tasks), partial score83.9%377.6%4
Chartography No tools61.6%66.6%5

Download image

Claude Sonnet 5.5Gemini 4 Hydrogen
Other benchmarks
Humanity's Last Exam No tools, full set (2,500 questions)56.9%No data
Humanity's Last Exam With tools, full set (2,500 questions)64.5%No data
HLE-Diamond No toolsNo data58.8%6
SWE-bench Pro Set not stated81.3%7No data
Terminal-Bench 4.070.6%8No data
AutomationBench 1.0.6 Private set44.7%9No data
AutomationBench 1.0.6 AutomationBench-AANo data76.1%10
OSWorld 2.1 Full set (108 tasks), partial score80.1%11No data
OSWorld 2.1 Full set (108 tasks), strict pass rate43.5%12No data
OSWorld 2.1 Offline set (82 tasks), strict pass rate48.8%13No data
FrontierCode 1.1 Main set52.1%14No data
FrontierCode 1.1 Extended set64.4%15No data
FrontierSWE v261.9%16No data
DeepSWE v1.171.0%17No data
Chartography With tools90.2%18No data
Agents' Last Exam v1.1 Score, all tasks (122)No data71.6%19

Notes

  1. Terminal-Bench Science 0.1, Claude Sonnet 5.5: Claude Code in --bare mode · max effort · standard error ±4.7 points
  2. Terminal-Bench Science 0.1, Gemini 4 Hydrogen: mini-swe-agent vision harness · highest thinking · average of 5 attempts per task
  3. OSWorld 2.1, Offline set (82 tasks), partial score, Claude Sonnet 5.5: max effort · mean of 5 attempts
  4. OSWorld 2.1, Offline set (82 tasks), partial score, Gemini 4 Hydrogen: Gemini CUA harness · highest thinking · max of 3 runs, one attempt per run
  5. Chartography, No tools, Gemini 4 Hydrogen: highest thinking
  6. HLE-Diamond, No tools, Gemini 4 Hydrogen: Run by Artificial Analysis · highest thinking
  7. SWE-bench Pro, Set not stated, Claude Sonnet 5.5: max effort · adaptive thinking · average of 5 trials
  8. Terminal-Bench 4.0, Claude Sonnet 5.5: adaptive thinking
  9. AutomationBench 1.0.6, Private set, Claude Sonnet 5.5: Run by Zapier · max effort · default fallbacks on
  10. AutomationBench 1.0.6, AutomationBench-AA, Gemini 4 Hydrogen: Run by Artificial Analysis · highest thinking
  11. OSWorld 2.1, Full set (108 tasks), partial score, Claude Sonnet 5.5: max effort · mean of 5 runs · September 10, 2026 task files
  12. OSWorld 2.1, Full set (108 tasks), strict pass rate, Claude Sonnet 5.5: max effort · mean of 5 runs · September 10, 2026 task files
  13. OSWorld 2.1, Offline set (82 tasks), strict pass rate, Claude Sonnet 5.5: max effort · mean of 5 attempts
  14. FrontierCode 1.1, Main set, Claude Sonnet 5.5: Run by Cognition · Claude Code harness · xhigh effort
  15. FrontierCode 1.1, Extended set, Claude Sonnet 5.5: Run by Cognition · Claude Code harness · xhigh effort
  16. FrontierSWE v2, Claude Sonnet 5.5: Run by Proximal · Proximal's agent harness · max reasoning effort · mean of 5 trials per task · 20-hour budget
  17. DeepSWE v1.1, Claude Sonnet 5.5: average of 5 trials
  18. Chartography, With tools, Claude Sonnet 5.5: max effort · adaptive thinking · average of 5 runs · container and image-cropping tool · Gemini 3.5 Flash grader
  19. Agents' Last Exam v1.1, Score, all tasks (122), Gemini 4 Hydrogen: Antigravity-CLI (agy) version 1.4.8 harness · highest thinking · 5-hour window · October 17, 2026 task files · safety filters on
Related

All comparisons