How Google and Thinking Machines Report HLE-Diamond
Gemini 4 Hydrogen and Inkling 2 Small report HLE-Diamond scores that Artificial Analysis ran without tools, the setting of the benchmark creators' main results.
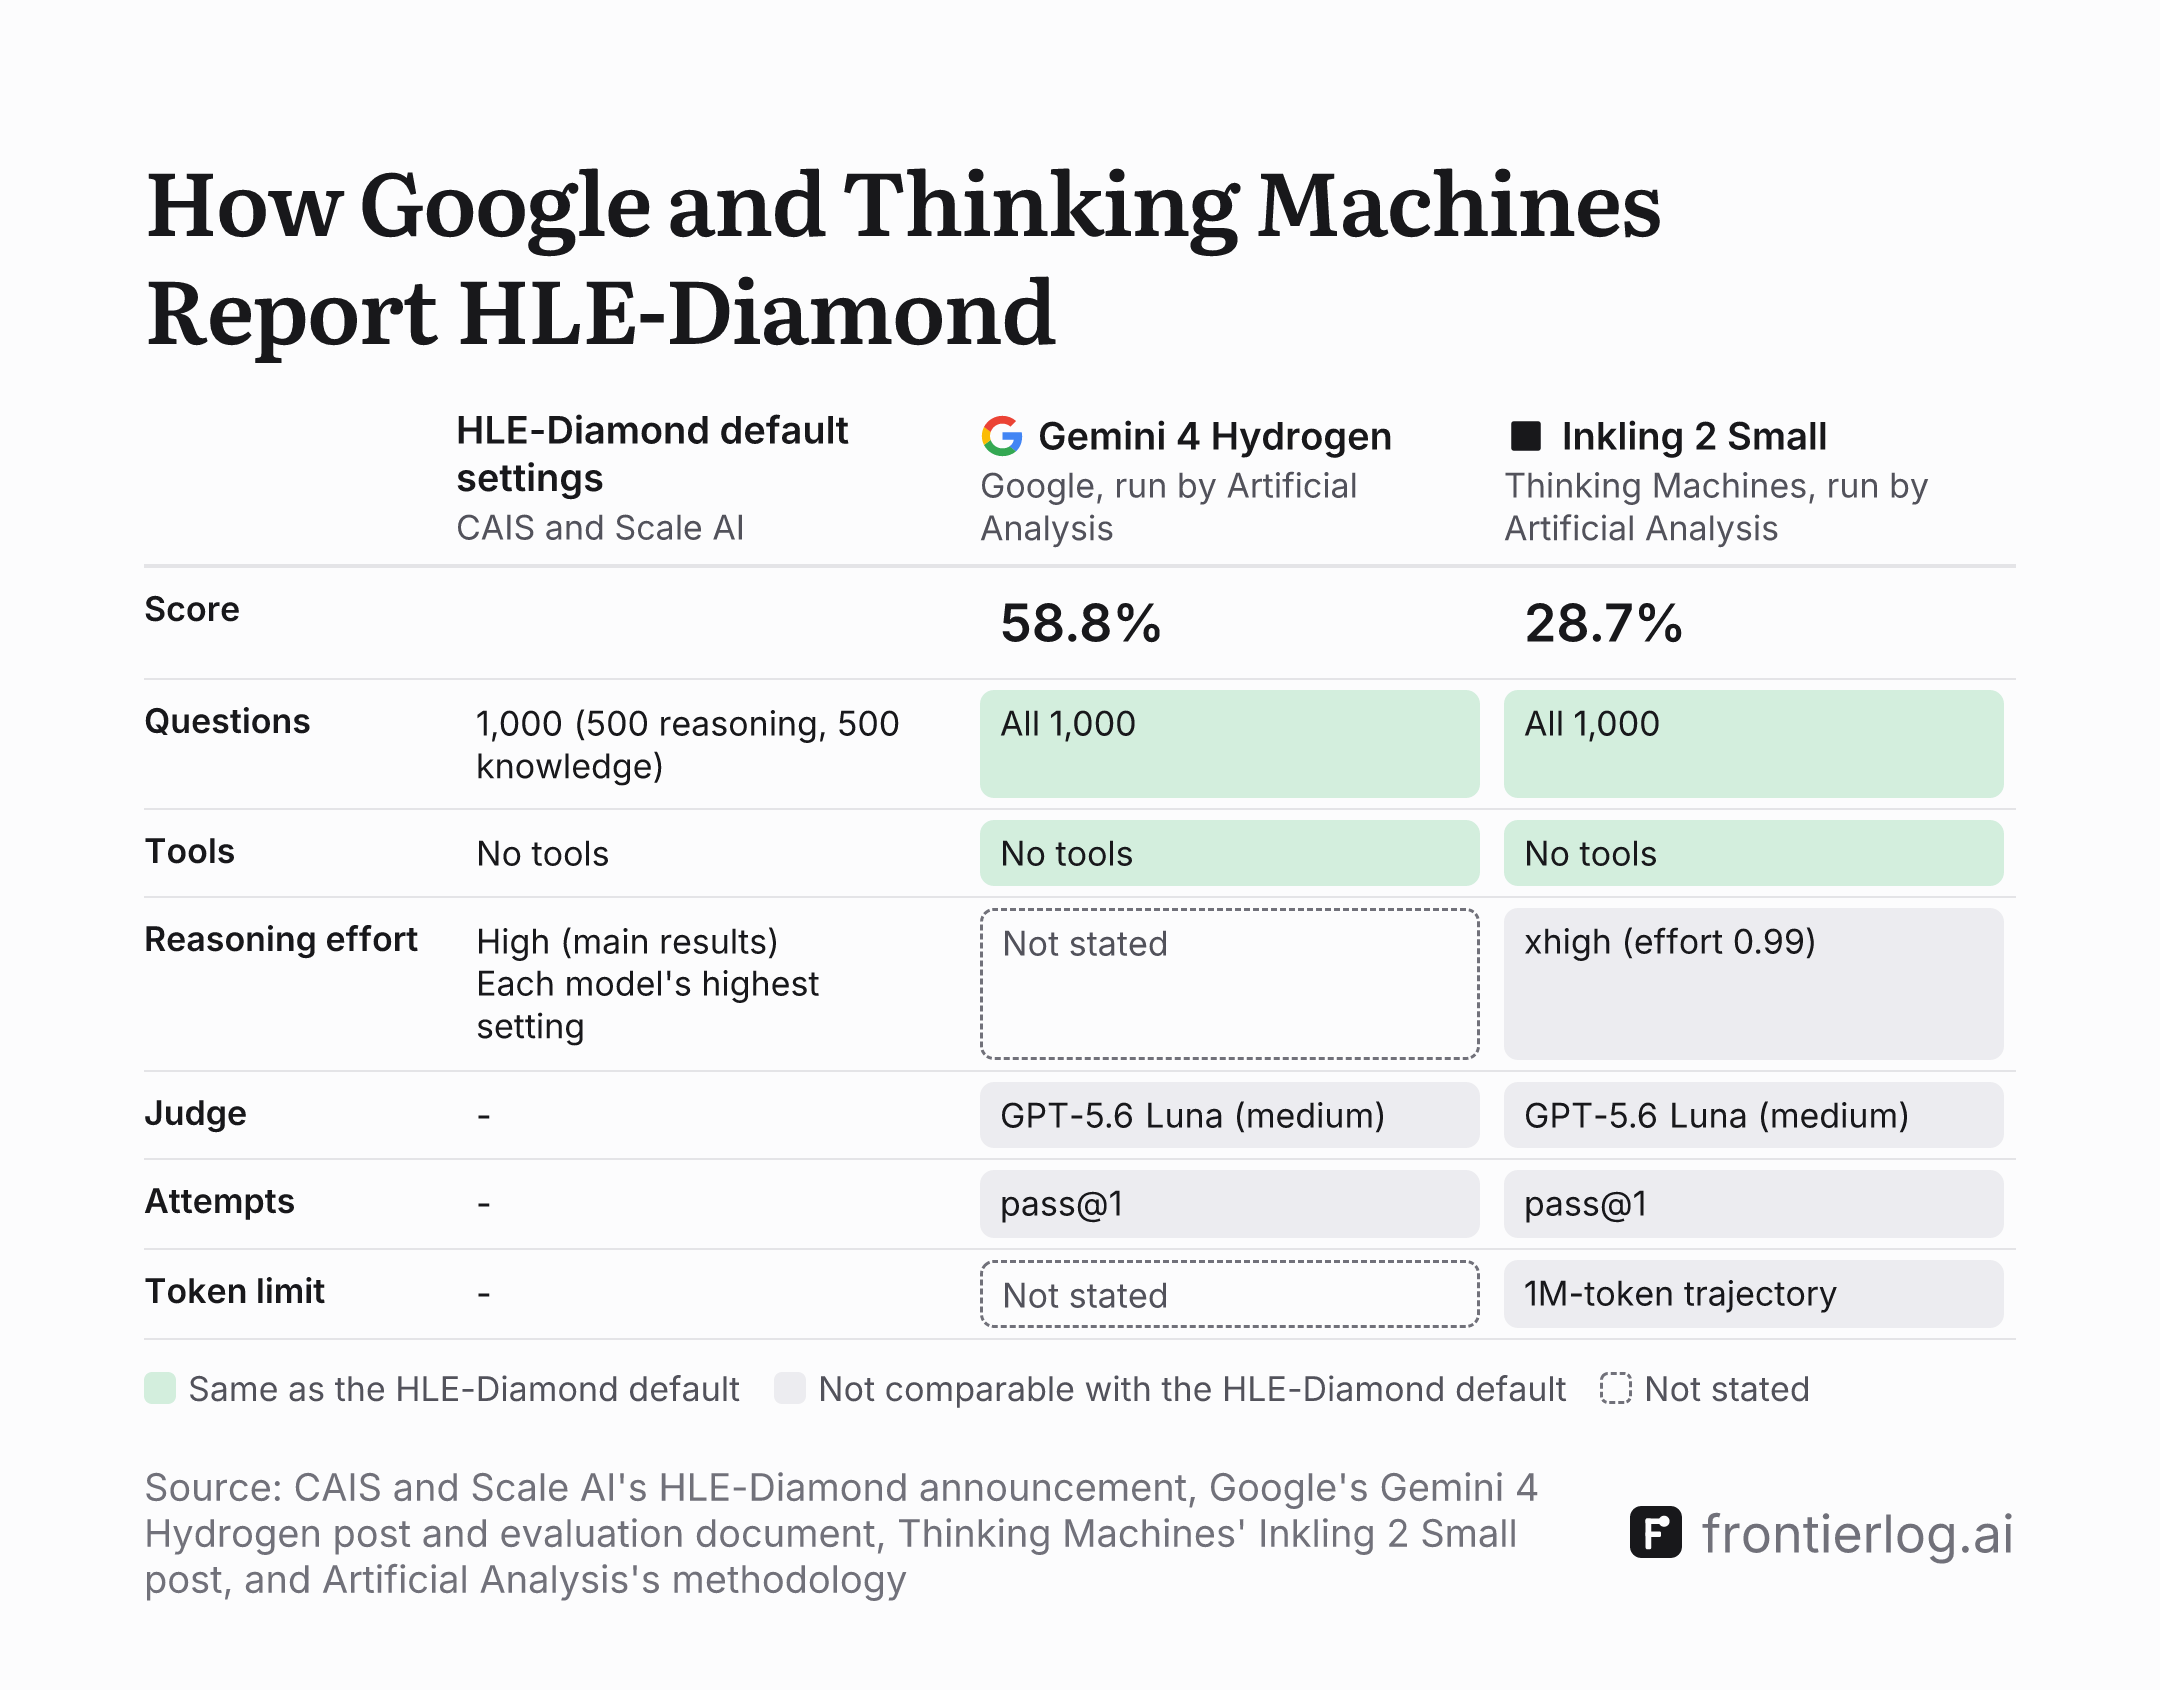
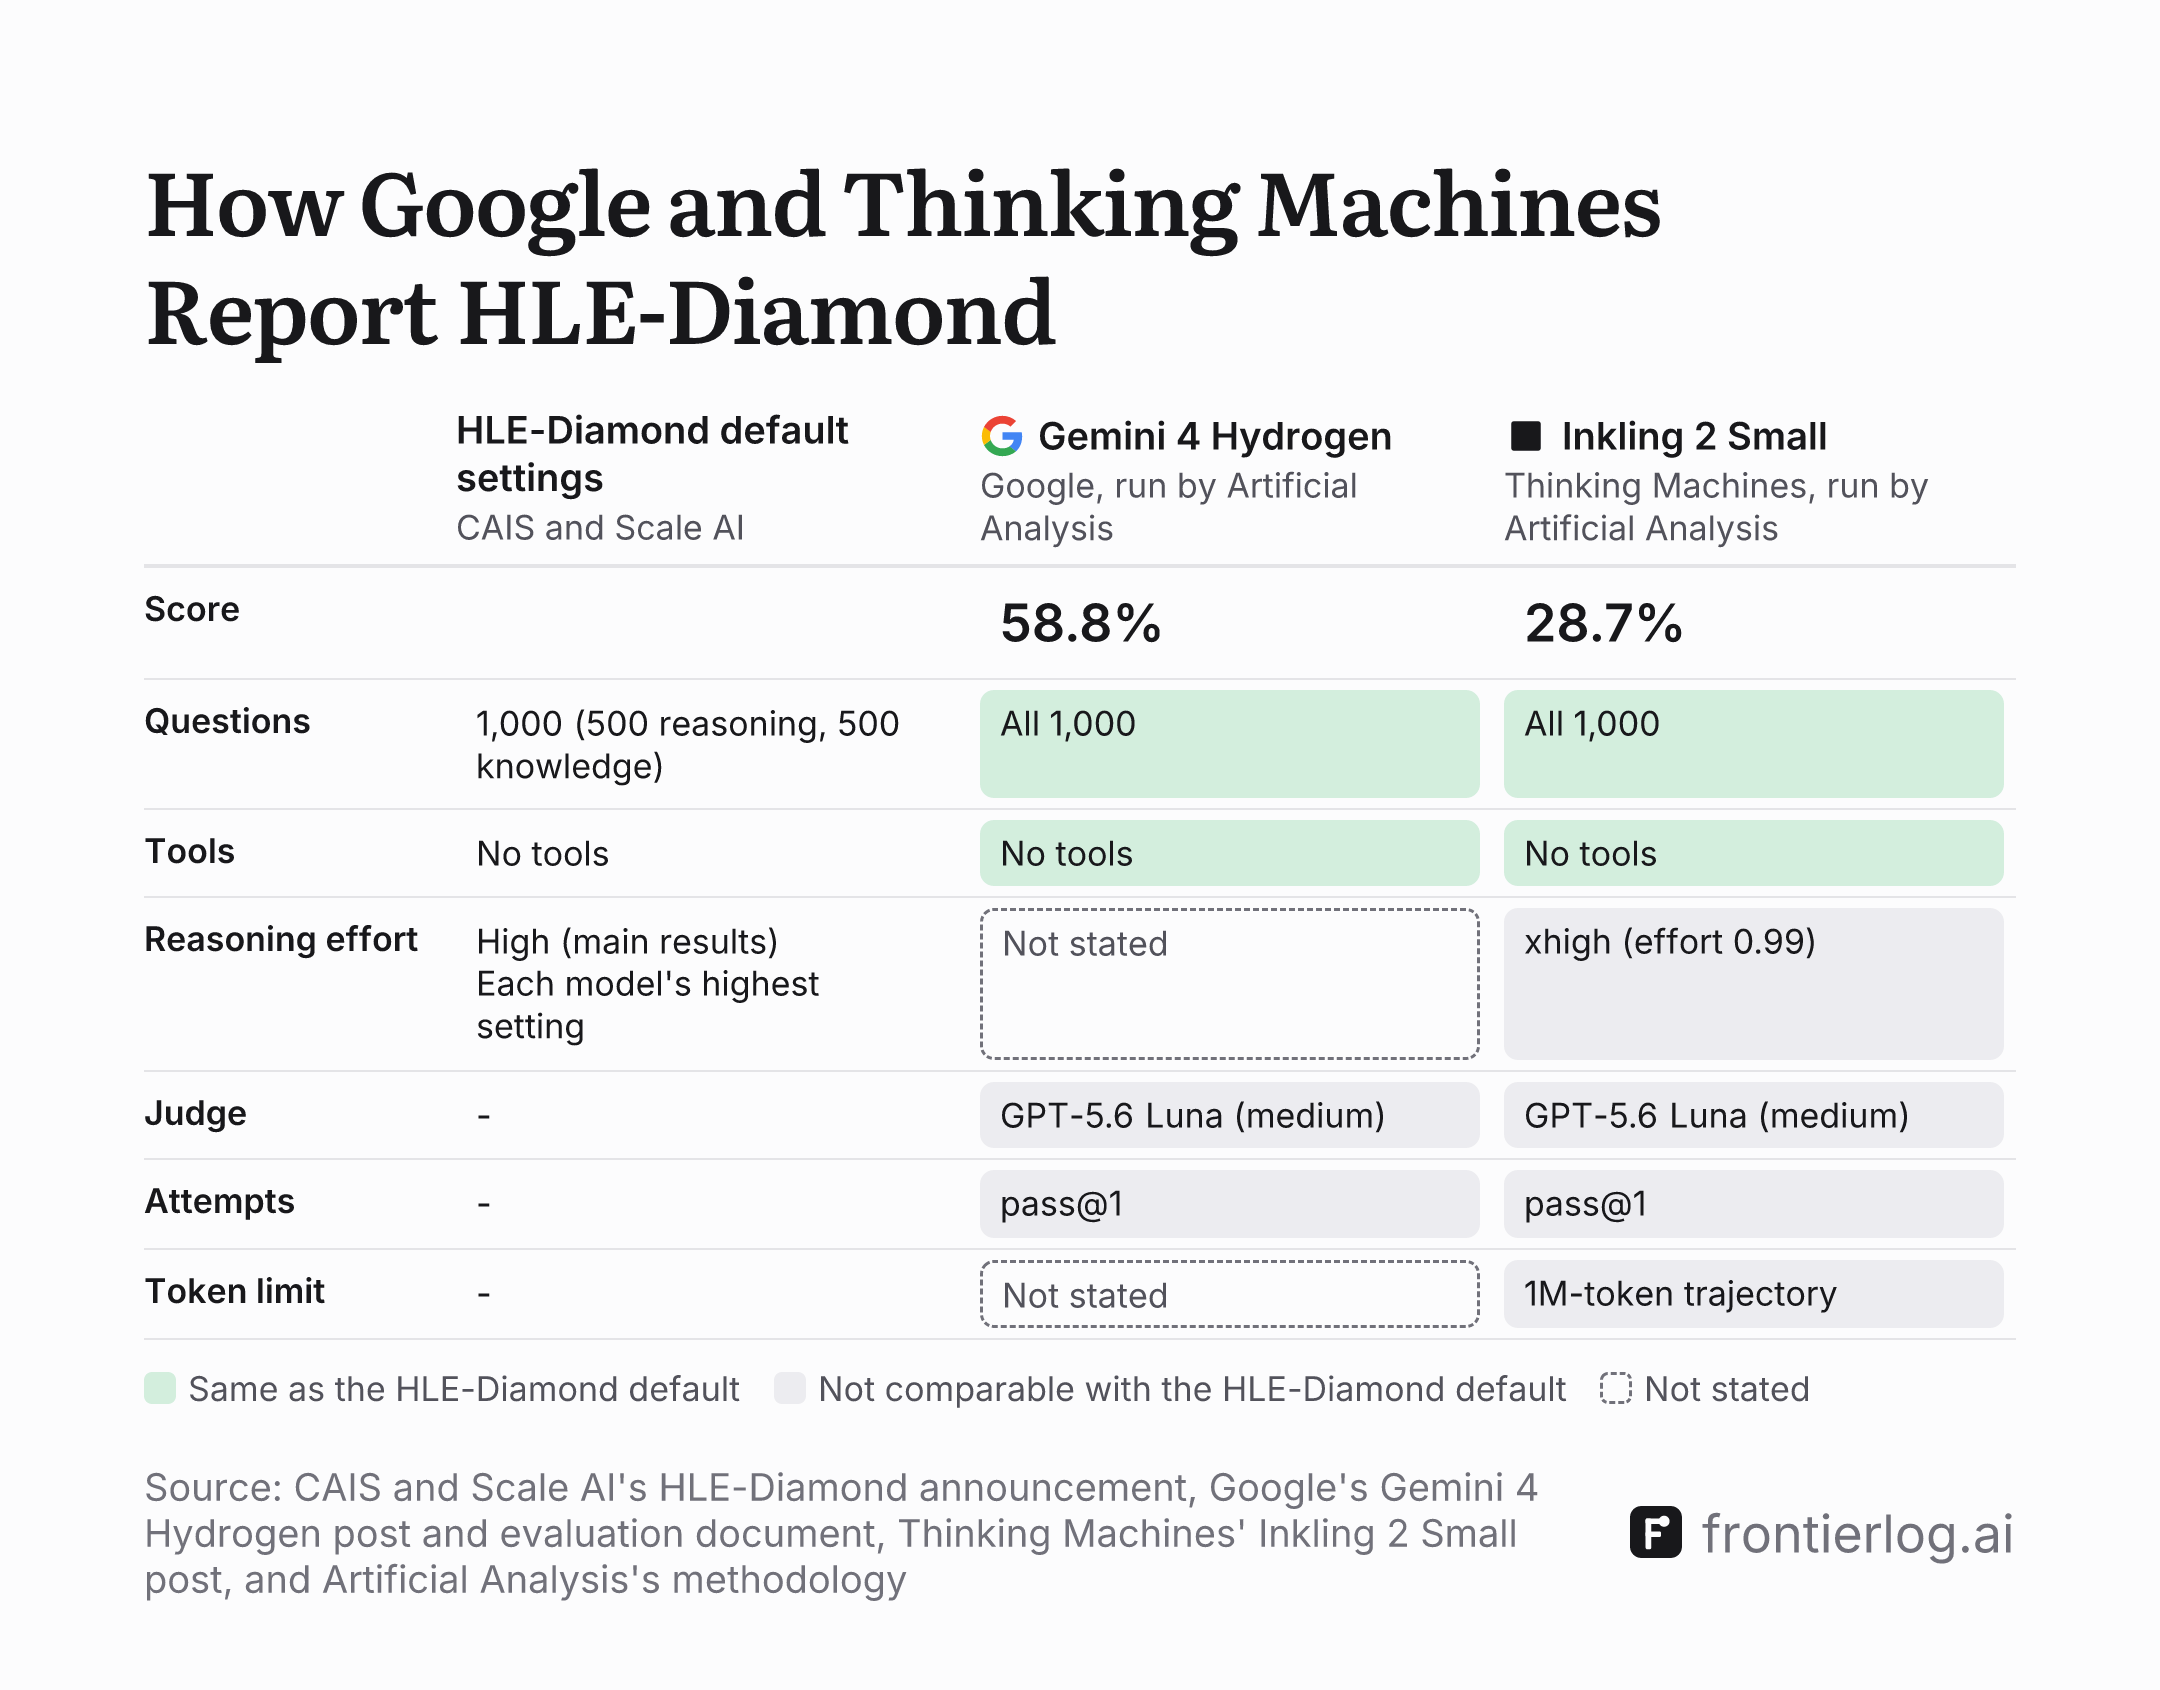
| Part | HLE-Diamond default settings (CAIS and Scale AI) | Gemini 4 Hydrogen (Google, run by Artificial Analysis) | Inkling 2 Small (Thinking Machines, run by Artificial Analysis) |
|---|---|---|---|
| Questions | 1,000 (500 reasoning, 500 knowledge) | All 1,000 | All 1,000 |
| Tools | No tools | No tools | No tools |
| Reasoning effort | High (main results). Each model's highest setting. | Not stated | xhigh (effort 0.99) |
| Judge | - | GPT-5.6 Luna (medium) | GPT-5.6 Luna (medium) |
| Attempts | - | pass@1 | pass@1 |
| Token limit | - | Not stated | 1M-token trajectory |
HLE-Diamond is a 1,000-question subset of Humanity's Last Exam that the Center for AI Safety and Scale AI released on Sep 22, 2026. The two groups compare models without tools and at reasoning high in their main results, their announcement says. Two labs have since put HLE-Diamond scores in their launch posts. Google's Gemini 4 Hydrogen scored 58.8% and Thinking Machines' Inkling 2 Small scored 28.7% on HLE-Diamond.
Both scores come from Artificial Analysis
Neither lab ran the benchmark itself. Google's evaluation document for Gemini 4 Hydrogen says that "HLE Diamond results are reported from the Artificial Analysis leaderboard." Google announced the model on Nov 12 in its launch post. Thinking Machines' Inkling 2 Small post, published on Nov 5, lists Artificial Analysis as the source of its HLE-Diamond scores.
The same questions and tools as the creators' default
Artificial Analysis says in its methodology that "We evaluate all 1,000 questions without tools." That matches the setting of the creators' main results. The creators also chart scores with web search and code, a setting they define in their evaluation notes.
Artificial Analysis uses GPT-5.6 Luna (medium) as its judge. Its scoring is pass@1, and it grades each answer with "the official HLE judge prompt and response format". The creators' announcement doesn't name a judge model or a number of attempts. The creators' original HLE evaluation code judges with o3-mini by default. Neither the announcement nor that code names the judge of the HLE-Diamond charts.
The two posts state effort differently
The creators chart every model at reasoning high for their main results. A "See reasoning max" toggle on the same charts shows each model at its highest available setting. Thinking Machines states that "All evals run at effort 0.99 (xhigh)" for Inkling 2 Small. Its post also sets "a 1M-token maximum trajectory limit" for every eval. The post gives effort as a number and names the level xhigh. The creators name reasoning levels and don't give effort as a number. Artificial Analysis's methodology doesn't state the effort of its Inkling 2 Small run.
Google's evaluation document says that Google ran its results at the highest thinking settings. Its note on HLE-Diamond says only that the result comes from the Artificial Analysis leaderboard. It doesn't state the thinking setting behind the 58.8%. Artificial Analysis's methodology doesn't list an effort level for each model. Google's launch post lists four thinking levels for the model: low, medium, high (the default) and xhigh. It cites Artificial Analysis's Intelligence Index at both high and xhigh.
Neither model is on the creators' chart
The main chart in the creators' announcement shows ten models, among them Gemini 4 Carbon and Gemini 4 Argon. None of the announcement's charts lists Gemini 4 Hydrogen or Inkling 2 Small.
HLE-Diamond, no tools
Sources
- Center for AI Safety and Scale AI, announcement, Sep 22, 2026lastexam.ai/blog/hle-diamond
- Center for AI Safety, evaluation notesgithub.com/centerforaisafety/hle/blob/main/docs/evaluation-with-tools.md
- Center for AI Safety, evaluation codegithub.com/centerforaisafety/hle/blob/main/hle_eval/run_judge_results.py
- Google, Nov 12, 2026Introducing Gemini 4 Hydrogen
- Google, Nov 12, 2026Gemini 4 Hydrogen Model evaluation: approach, methodology & results
- Thinking Machines, Nov 5, 2026Introducing Inkling 2 Small
- Artificial Analysis, methodology pageartificialanalysis.ai/methodology/intelligence-benchmarking