Frontier Log

GPT-6.1 Sol and Terra Are Still Behind GPT-6 Astra

On OpenAI's own charts, the cheaper GPT-6.1 Sol and GPT-6.1 Terra score below GPT-6 Astra on most benchmarks. Each matches it on one.
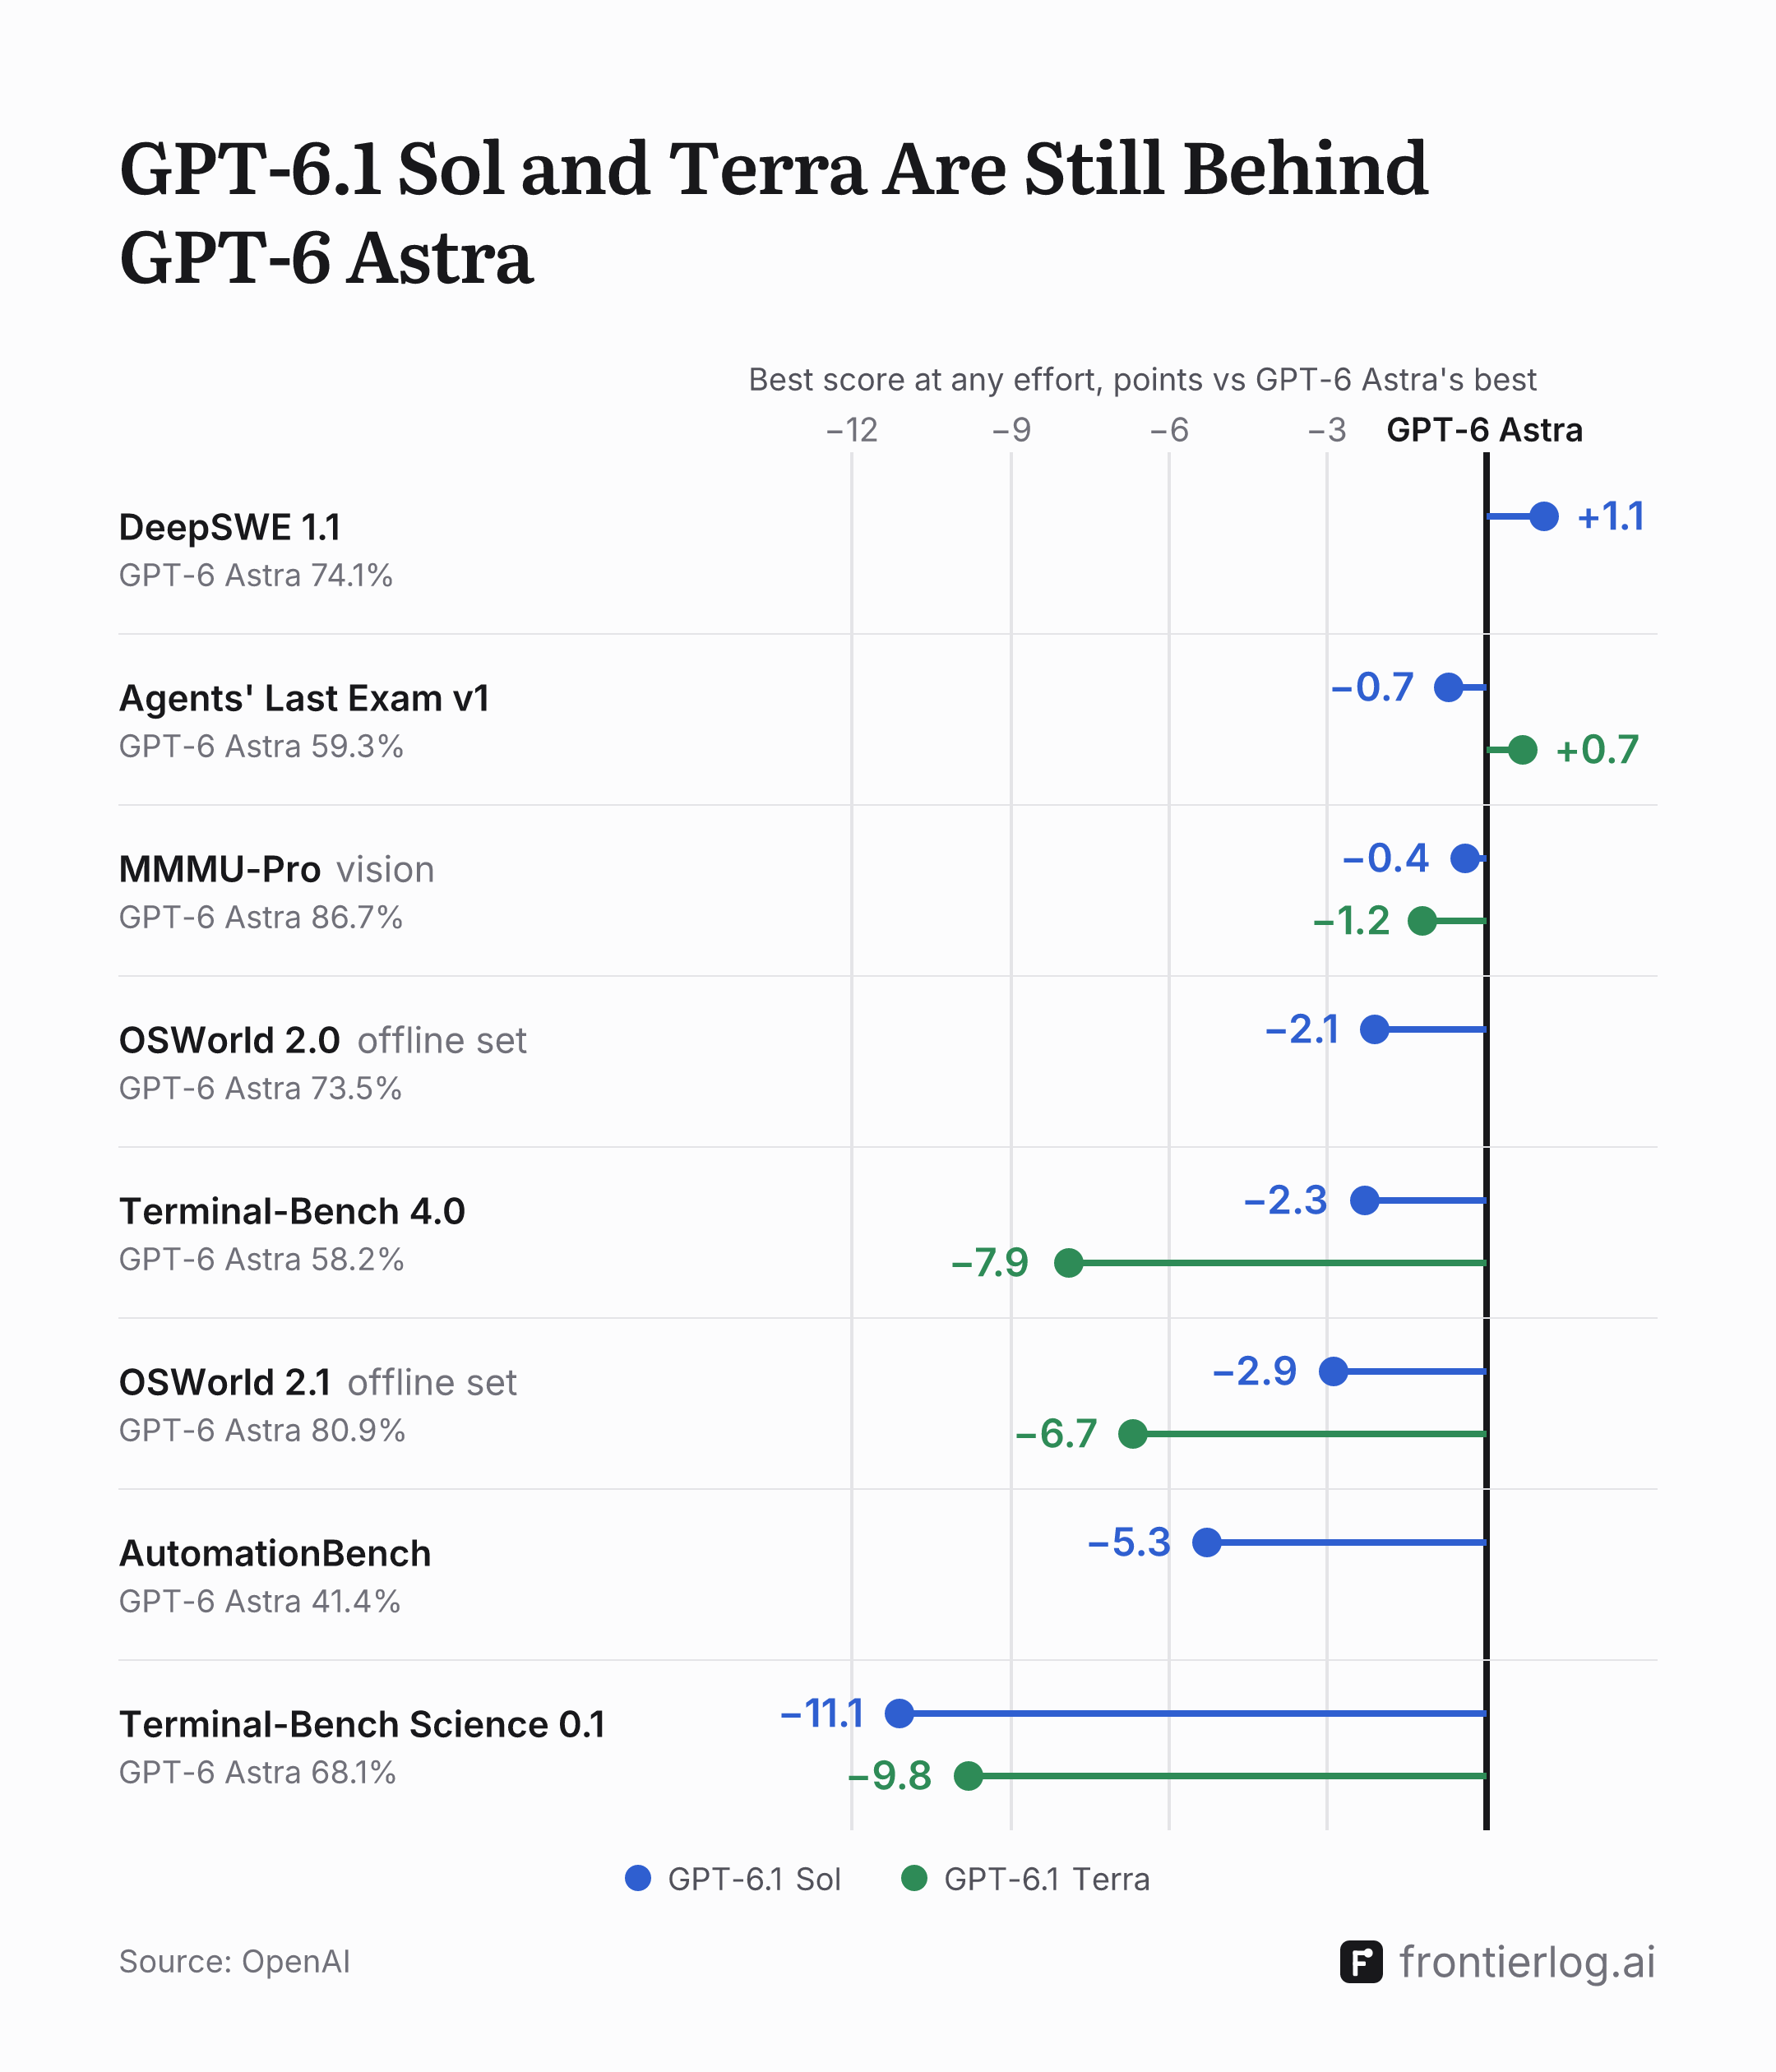
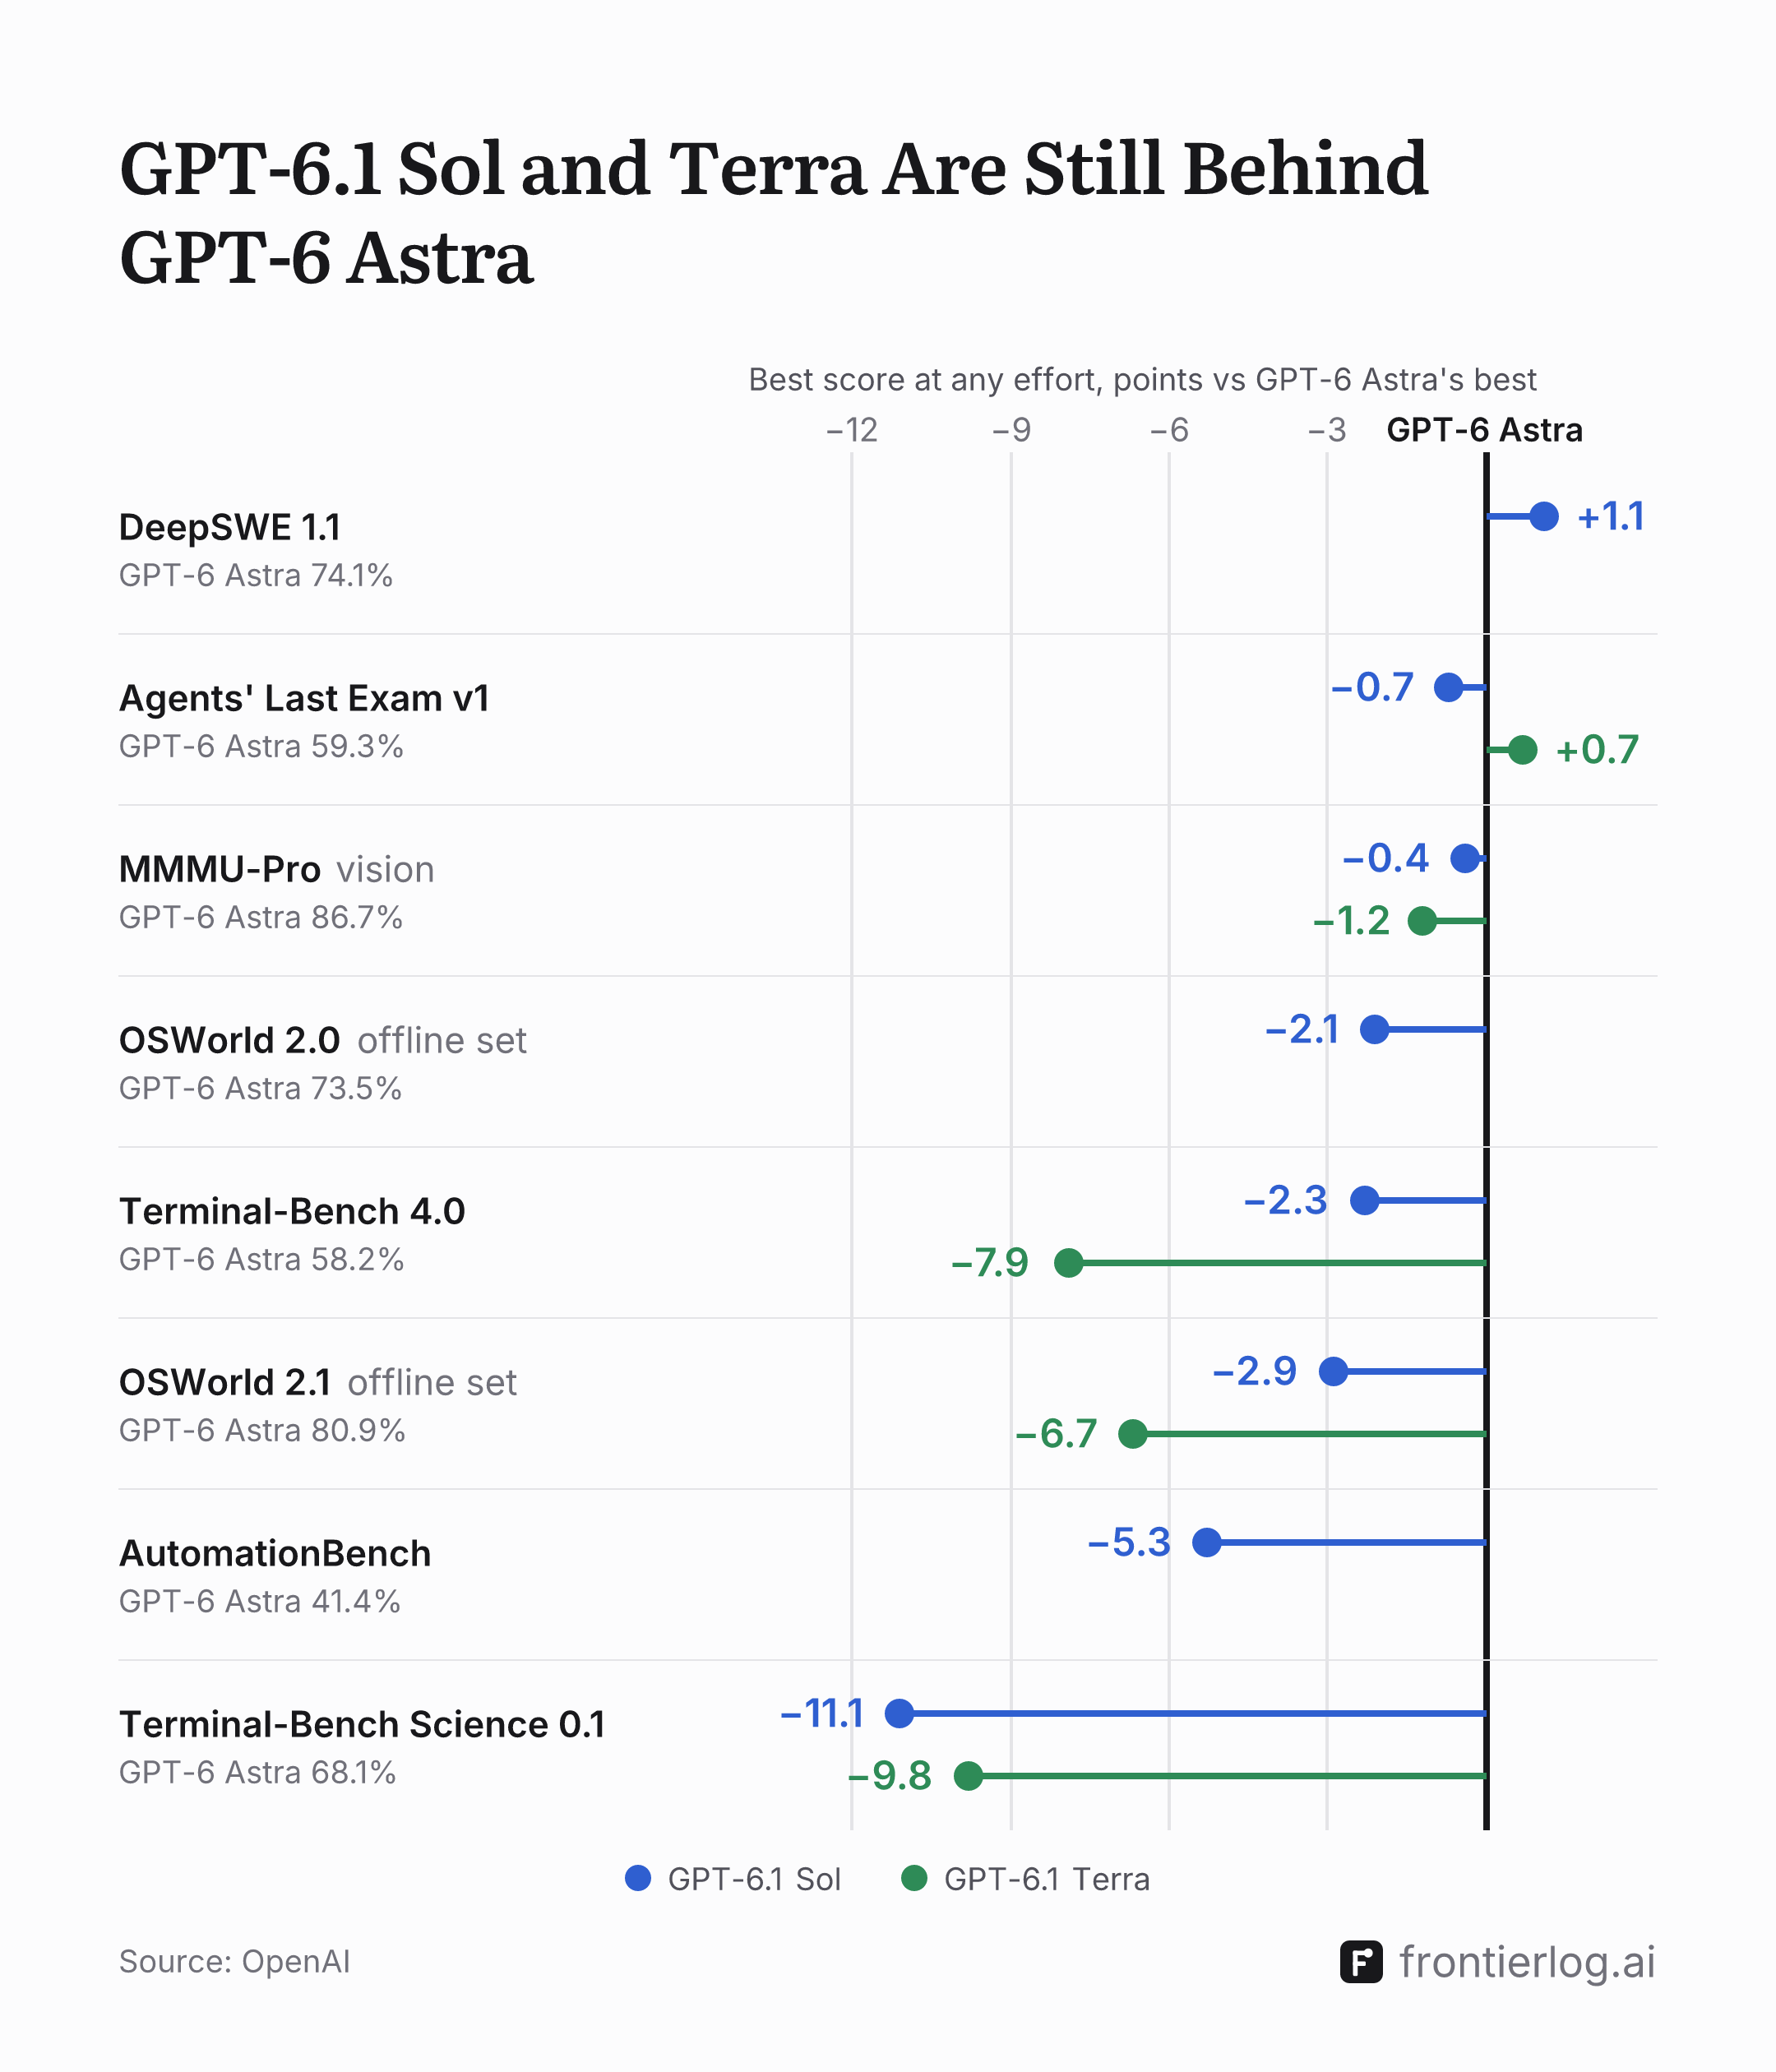
Lollipop chart of points above or below GPT-6 Astra's best score, per benchmark. GPT-6.1 Sol: DeepSWE 1.1 +1.1, Agents' Last Exam v1 −0.7, MMMU-Pro −0.4, OSWorld 2.0 −2.1, Terminal-Bench 4.0 −2.3, OSWorld 2.1 −2.9, AutomationBench −5.3, Terminal-Bench Science 0.1 −11.1. GPT-6.1 Terra: Agents' Last Exam v1 +0.7, MMMU-Pro −1.2, Terminal-Bench 4.0 −7.9, OSWorld 2.1 −6.7, Terminal-Bench Science 0.1 −9.8.
Each row compares a model's best score at any reasoning effort with GPT-6 Astra's best on the same chart, from OpenAI's launch posts for GPT-6.1 Sol (Sep 29) and GPT-6.1 Terra (Oct 26). Sol scores just above Astra on DeepSWE 1.1, and Terra on Agents' Last Exam v1. Download

Beside its flagship, GPT-6 Astra, OpenAI sells cheaper models. Two of them are GPT-6.1 Sol, launched on Sep 29, and GPT-6.1 Terra, launched on Oct 26. Their launch posts chart them against Astra on eight benchmarks this site tracks. Sol scores below Astra on seven of its eight, and Terra on four of its five.

BenchmarkGPT-6 AstraGPT-6.1 SolGPT-6.1 Terra
DeepSWE 1.174.1%75.2% (+1.1)–
Agents' Last Exam v159.3%58.6% (−0.7)60.0% (+0.7)
MMMU-Pro, vision86.7%86.3% (−0.4)85.5% (−1.2)
OSWorld 2.0, offline set73.5%71.4% (−2.1)–
Terminal-Bench 4.058.2%55.9% (−2.3)50.3% (−7.9)
OSWorld 2.1, offline set80.9%78.0% (−2.9)74.2% (−6.7)
AutomationBench41.4%36.1% (−5.3)–
Terminal-Bench Science 0.168.1%57.0% (−11.1)58.3% (−9.8)

Each model matches Astra on one benchmark

Sol scores 75.2% on DeepSWE 1.1 at high effort, 1.1 points above Astra's 74.1%, in the Sol launch post. OpenAI wrote there that Sol "matches GPT-6 Astra at roughly one-fifth of the cost." Terra scores 60.0% on Agents' Last Exam v1 at maximum effort, 0.7 points above Astra's 59.3%, in the Terra launch post. OpenAI wrote that Terra "performs on par with GPT-6 Astra at only one-tenth its price per token."

Astra stays ahead on the rest

The largest gaps are on Terminal-Bench Science 0.1. Astra scores 68.1% there at maximum effort, Sol 57.0% and Terra 58.3%. OpenAI wrote in the Sol post that Astra "should be used for the most difficult scientific research tasks."

On Terminal-Bench 4.0, Terra's best is 50.3%, 7.9 points below Astra's 58.2%. The Terra post says: "For the most complex coding tasks, GPT-6.1 Sol and GPT-6 Astra remain the better choice." Sol is 5.3 points behind Astra on AutomationBench and 2.9 points behind on the offline set of OSWorld 2.1, where Terra is 6.7 points behind.

The Sol post also charts GDP.pdf, a benchmark this site does not track, where Sol scores just below Astra. Both posts chart OpenAI's internal test of factual errors on difficult prompts, where Astra makes the fewest errors of the three.

A fifth and a tenth of the price

Astra costs $10 per million input tokens and $50 per million output tokens on OpenAI's pricing page. Sol costs $2 and $10, a fifth of that. Terra costs $1 and $5, a tenth. Per task, the gap can be smaller. On Terminal-Bench Science at maximum effort, Sol costs $5.47 per task and Astra $23.80, OpenAI said in the Sol post.

How the scores were compared

Each row of the chart compares a model's best score at any reasoning effort with Astra's best on the same OpenAI chart. Astra's own launch post on Sep 3 gives it lower scores on three of these benchmarks: 57.9% on Terminal-Bench 4.0, 64.6% on Terminal-Bench Science 0.1 and 72.6% on the offline set of OSWorld 2.0, in its results tables. Sol and Terra are behind those figures too.

Terminal-Bench's own leaderboard lists Sol at 58.2% on Terminal-Bench 4.0, the same as Astra, above the 55.9% OpenAI charts for Sol in the Terra post. It does not list Terra. The benchmark makers' leaderboards for Terminal-Bench Science, DeepSWE and AutomationBench list Astra but neither 6.1 model, as of Nov 7.

DeepSWE 1.1

ModelScoreSources
GPT-6 Astra74.1%AnnouncementCoding table, row 'DeepSWE v1.1', column 'GPT‑6 Astra'
GPT-6.1 Sol75.2%AnnouncementDeepSWE v1.1 chart under "Coding" (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'High', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)

Agents' Last Exam v1

ModelScoreSources
GPT-6 Astra59.3%Announcement'Computer Use' eval table, row 'Agents' Last Exam', column 'GPT-6 Astra'
GPT-6.1 Sol58.6%Announcement"Agents' Last Exam v1" chart (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Terra60.0%Announcement"Agents' Last Exam v1" chart (score vs cost per task; no value labels): point 'GPT-6.1 Terra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)

MMMU-Pro, vision

ModelScoreSources
GPT-6 Astra86.7%Announcement"MMMU-Pro (Vision)" chart (score vs cost per task; no value labels): point 'GPT-6 Astra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Sol86.3%Announcement"MMMU-Pro (Vision)" chart (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Terra85.5%Announcement"MMMU-Pro (Vision)" chart (score vs cost per task; no value labels): point 'GPT-6.1 Terra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)

OSWorld 2.0, offline set

ModelScoreSources
GPT-6 Astra73.5%Announcement"OSWorld 2.0, offline set" chart under "Computer use" (score vs cost per task; no value labels): point 'GPT-6 Astra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Sol71.4%Announcement"OSWorld 2.0, offline set" chart under "Computer use" (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)

Terminal-Bench 4.0

ModelScoreSources
GPT-6 Astra58.2%Announcement"Terminal-Bench 4.0" chart (score vs cost per task; no value labels): point 'GPT-6 Astra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Sol55.9%Announcement"Terminal-Bench 4.0" chart (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Terra50.3%Announcement'A significant step up on factuality and coding' section, paragraph introducing Terminal-Bench 4.0, sentence 'At maximum reasoning effort, GPT-6.1 Terra solves ... of tasks'

OSWorld 2.1, offline set

ModelScoreSources
GPT-6 Astra80.9%Announcement"OSWorld 2.1, offline set" chart (score vs cost per task; no value labels): point 'GPT-6 Astra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Sol78.0%Announcement"OSWorld 2.1, offline set" chart (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Terra74.2%Announcement"OSWorld 2.1, offline set" chart (score vs cost per task; no value labels): point 'GPT-6.1 Terra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)

AutomationBench

ModelScoreSources
GPT-6 Astra41.4%AnnouncementProfessional table, row 'AutomationBench', column 'GPT‑6 Astra'
GPT-6.1 Sol36.1%AnnouncementAutomationBench chart under "Professional work" (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)

Terminal-Bench Science 0.1

ModelScoreSources
GPT-6 Astra68.1%Announcement'Scientific research' section, paragraph after the Terminal-Bench Science 0.1 cost sentence: 'GPT-6 Astra still achieves the highest score among the models tested at ...'
GPT-6.1 Sol57.0%Announcement"Terminal-Bench Science 0.1" chart under "Scientific research" (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)
GPT-6.1 Terra58.3%Announcement"Terminal-Bench-Science 0.1" chart (score vs cost per task; no value labels): point 'GPT-6.1 Terra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point)

GPT-6 Astra in its own launch post

ModelScoreSources
GPT-6 Astra57.9%AnnouncementCoding table, row 'Terminal-Bench 4.0', column 'GPT‑6 Astra'
GPT-6 Astra64.6%AnnouncementAcademic table, row 'Terminal-Bench Science 0.1', column 'GPT‑6 Astra'
GPT-6 Astra72.6%AnnouncementComputer Use table, row 'OSWorld 2.0 (v2026.08.08, offline set, partial score)', column 'GPT‑6 Astra'

Input price, $ per 1M tokens

ModelValueSources
GPT-6 Astra10$AnnouncementFlagship models table, Standard tab, Short context (≤272K input tokens), 'All models' expanded; row gpt-6-astra; column Input
GPT-6.1 Sol2$AnnouncementFlagship models table, Standard tab, Short context (≤272K input tokens), 'All models' expanded; row gpt-6.1-sol; column Input
GPT-6.1 Terra1$AnnouncementFlagship models table, Standard tab, Short context (≤272K input tokens), 'All models' expanded; row gpt-6.1-terra; column Input

Output price, $ per 1M tokens

ModelValueSources
GPT-6 Astra50$AnnouncementFlagship models table, Standard tab, Short context (≤272K input tokens), 'All models' expanded; row gpt-6-astra; column Output
GPT-6.1 Sol10$AnnouncementFlagship models table, Standard tab, Short context (≤272K input tokens), 'All models' expanded; row gpt-6.1-sol; column Output
GPT-6.1 Terra5$AnnouncementFlagship models table, Standard tab, Short context (≤272K input tokens), 'All models' expanded; row gpt-6.1-terra; column Output

Cost per task, Terminal-Bench Science 0.1 at maximum effort, $

ModelValueSources
GPT-6 AstraGPT-6 Astra23.8$Announcement'Scientific research' section: '... compared with $23.21 for Opus 5.5 and $23.80 for Astra'
GPT-6.1 SolGPT-6.1 Sol5.47$Announcement'Scientific research' section: 'At maximum effort, GPT-6.1 Sol costs $5.47 per task on average'

Sources

Models

Related

Tags