Claude and GPT models on FrontierCode 2.0
Changed by Cognition on
Said it had changedPrinted a new figure
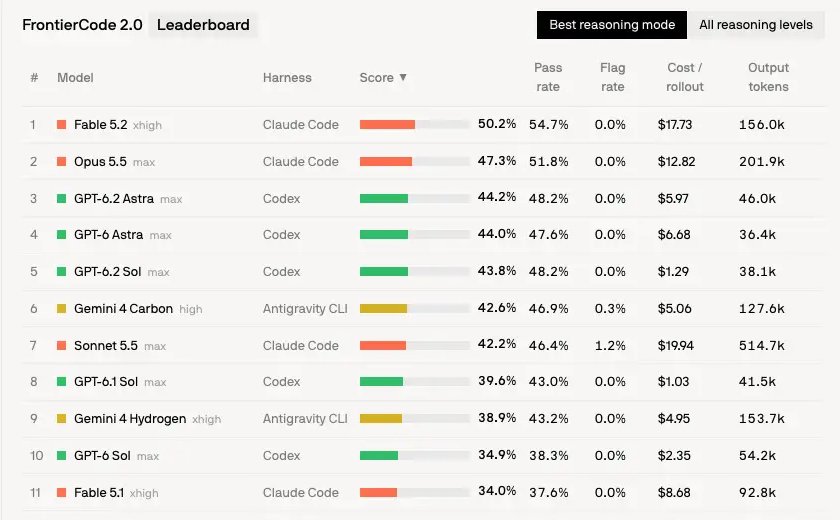
Cognition updated the cheating scanner on its FrontierCode 2.0 leaderboard to remove false positives on Nov 11, 2026, and rescored all results. At xhigh effort, Claude Fable 5.2 rose from 49.1% to 50.2%.
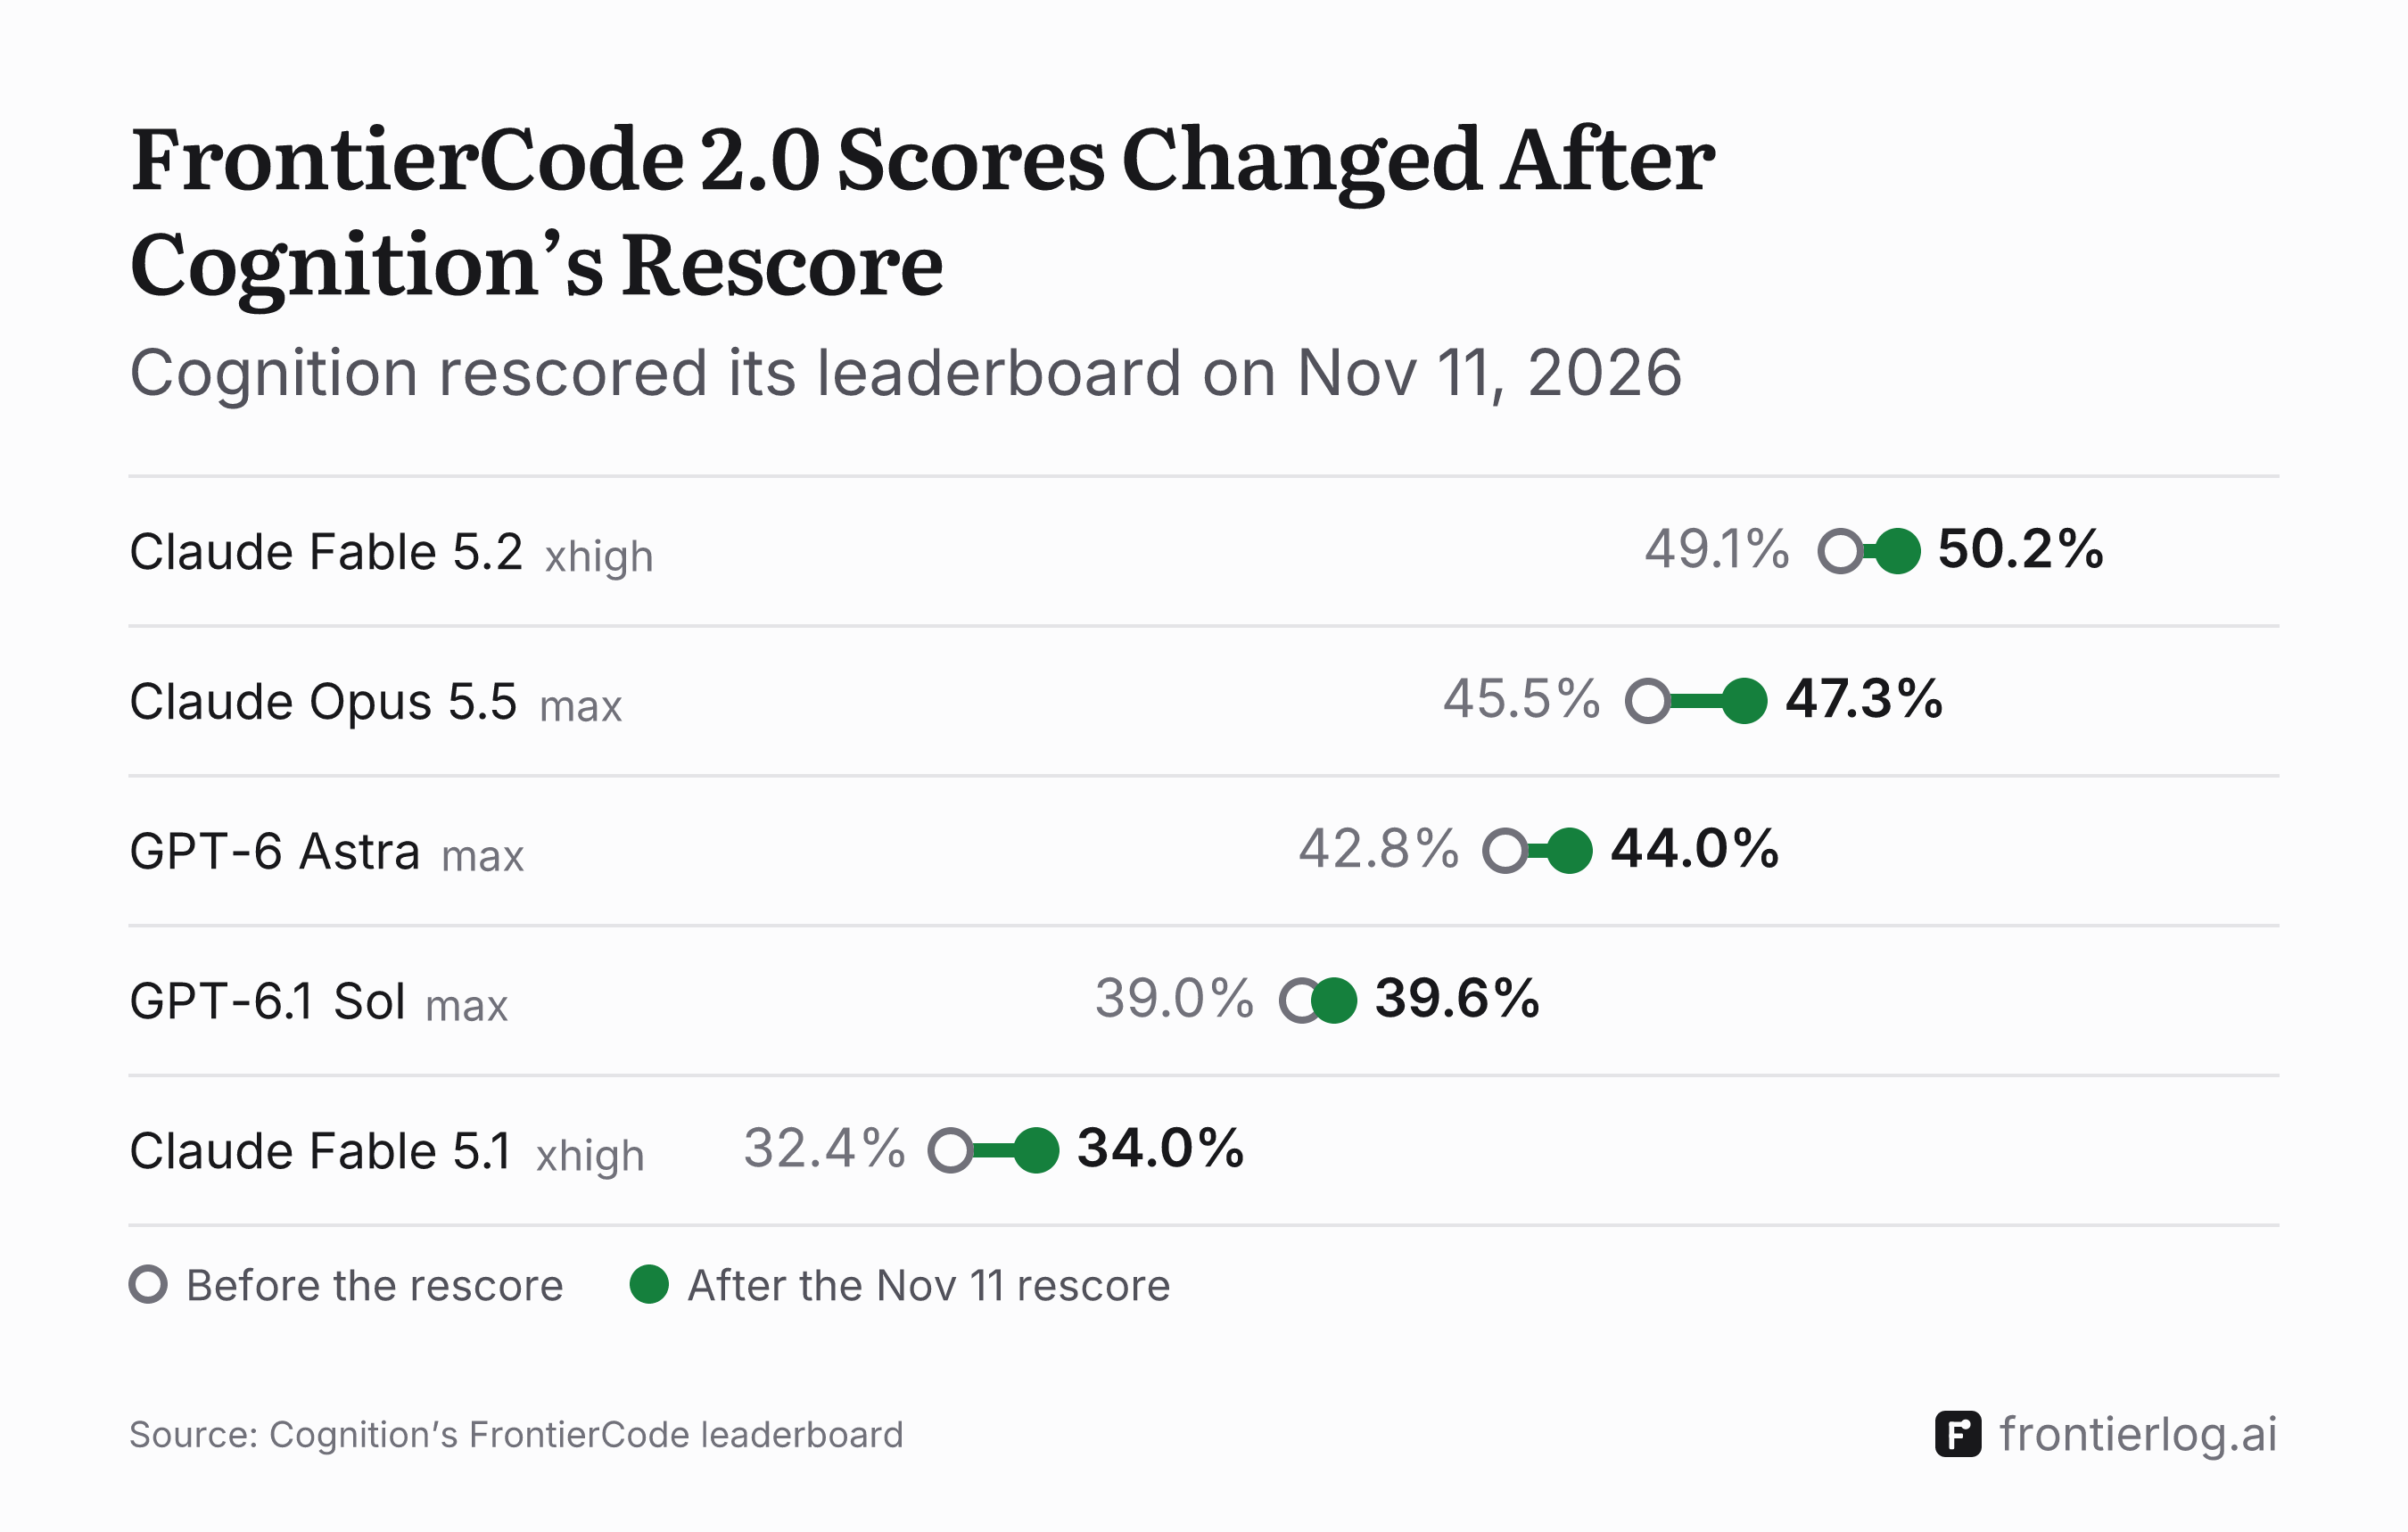
At max effort, Claude Opus 5.5 rose from 45.5% to 47.3%. GPT-6 Astra rose from 42.8% to 44.0%, and GPT-6.1 Sol rose from 39.0% to 39.6%. At xhigh effort, Claude Fable 5.1 rose from 32.4% to 34.0%.
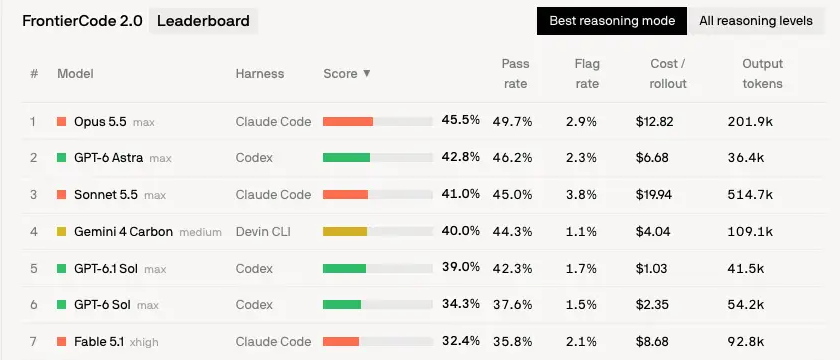
The earlier figures for those four models are from Frontier Log’s copy of the leaderboard of Oct 31, 2026. Cognition added Fable 5.2 on Nov 9, and its earlier figure is from Anthropic’s Claude Fable 5.2 post. That post prints the earlier figures for Opus 5.5 and Fable 5.1, and OpenAI’s GPT-6.2 post prints them for GPT-6 Astra and GPT-6.1 Sol.
Comparison
Claude Fable 5.2 (xhigh)
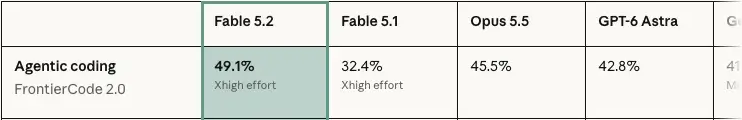
Claude Opus 5.5 (max), GPT-6 Astra (max), GPT-6.1 Sol (max), Claude Fable 5.1 (xhigh)
- FrontierCode Leaderboardcognition.com
- Introducing Claude Fable 5.2 and Claude Mythos 5.2anthropic.com
- Introducing GPT-6.2 Astra and Solopenai.com