Frontier Log

Nemotron 3.5 Bolt E4B on X

NVIDIA · launched AnnouncementEvent

The launch vibe for Nemotron 3.5 Bolt E4B was mostly positive among people who ran it on their own Macs, phones, Jetson boards and GPUs, who praised its speed and tool calls for its size; the doubts were agent runs that looped, slow phones and CPUs, and a download bigger than advertised. Of the 10 posts quoted here, 6 are positive, 2 mixed and 2 negative.
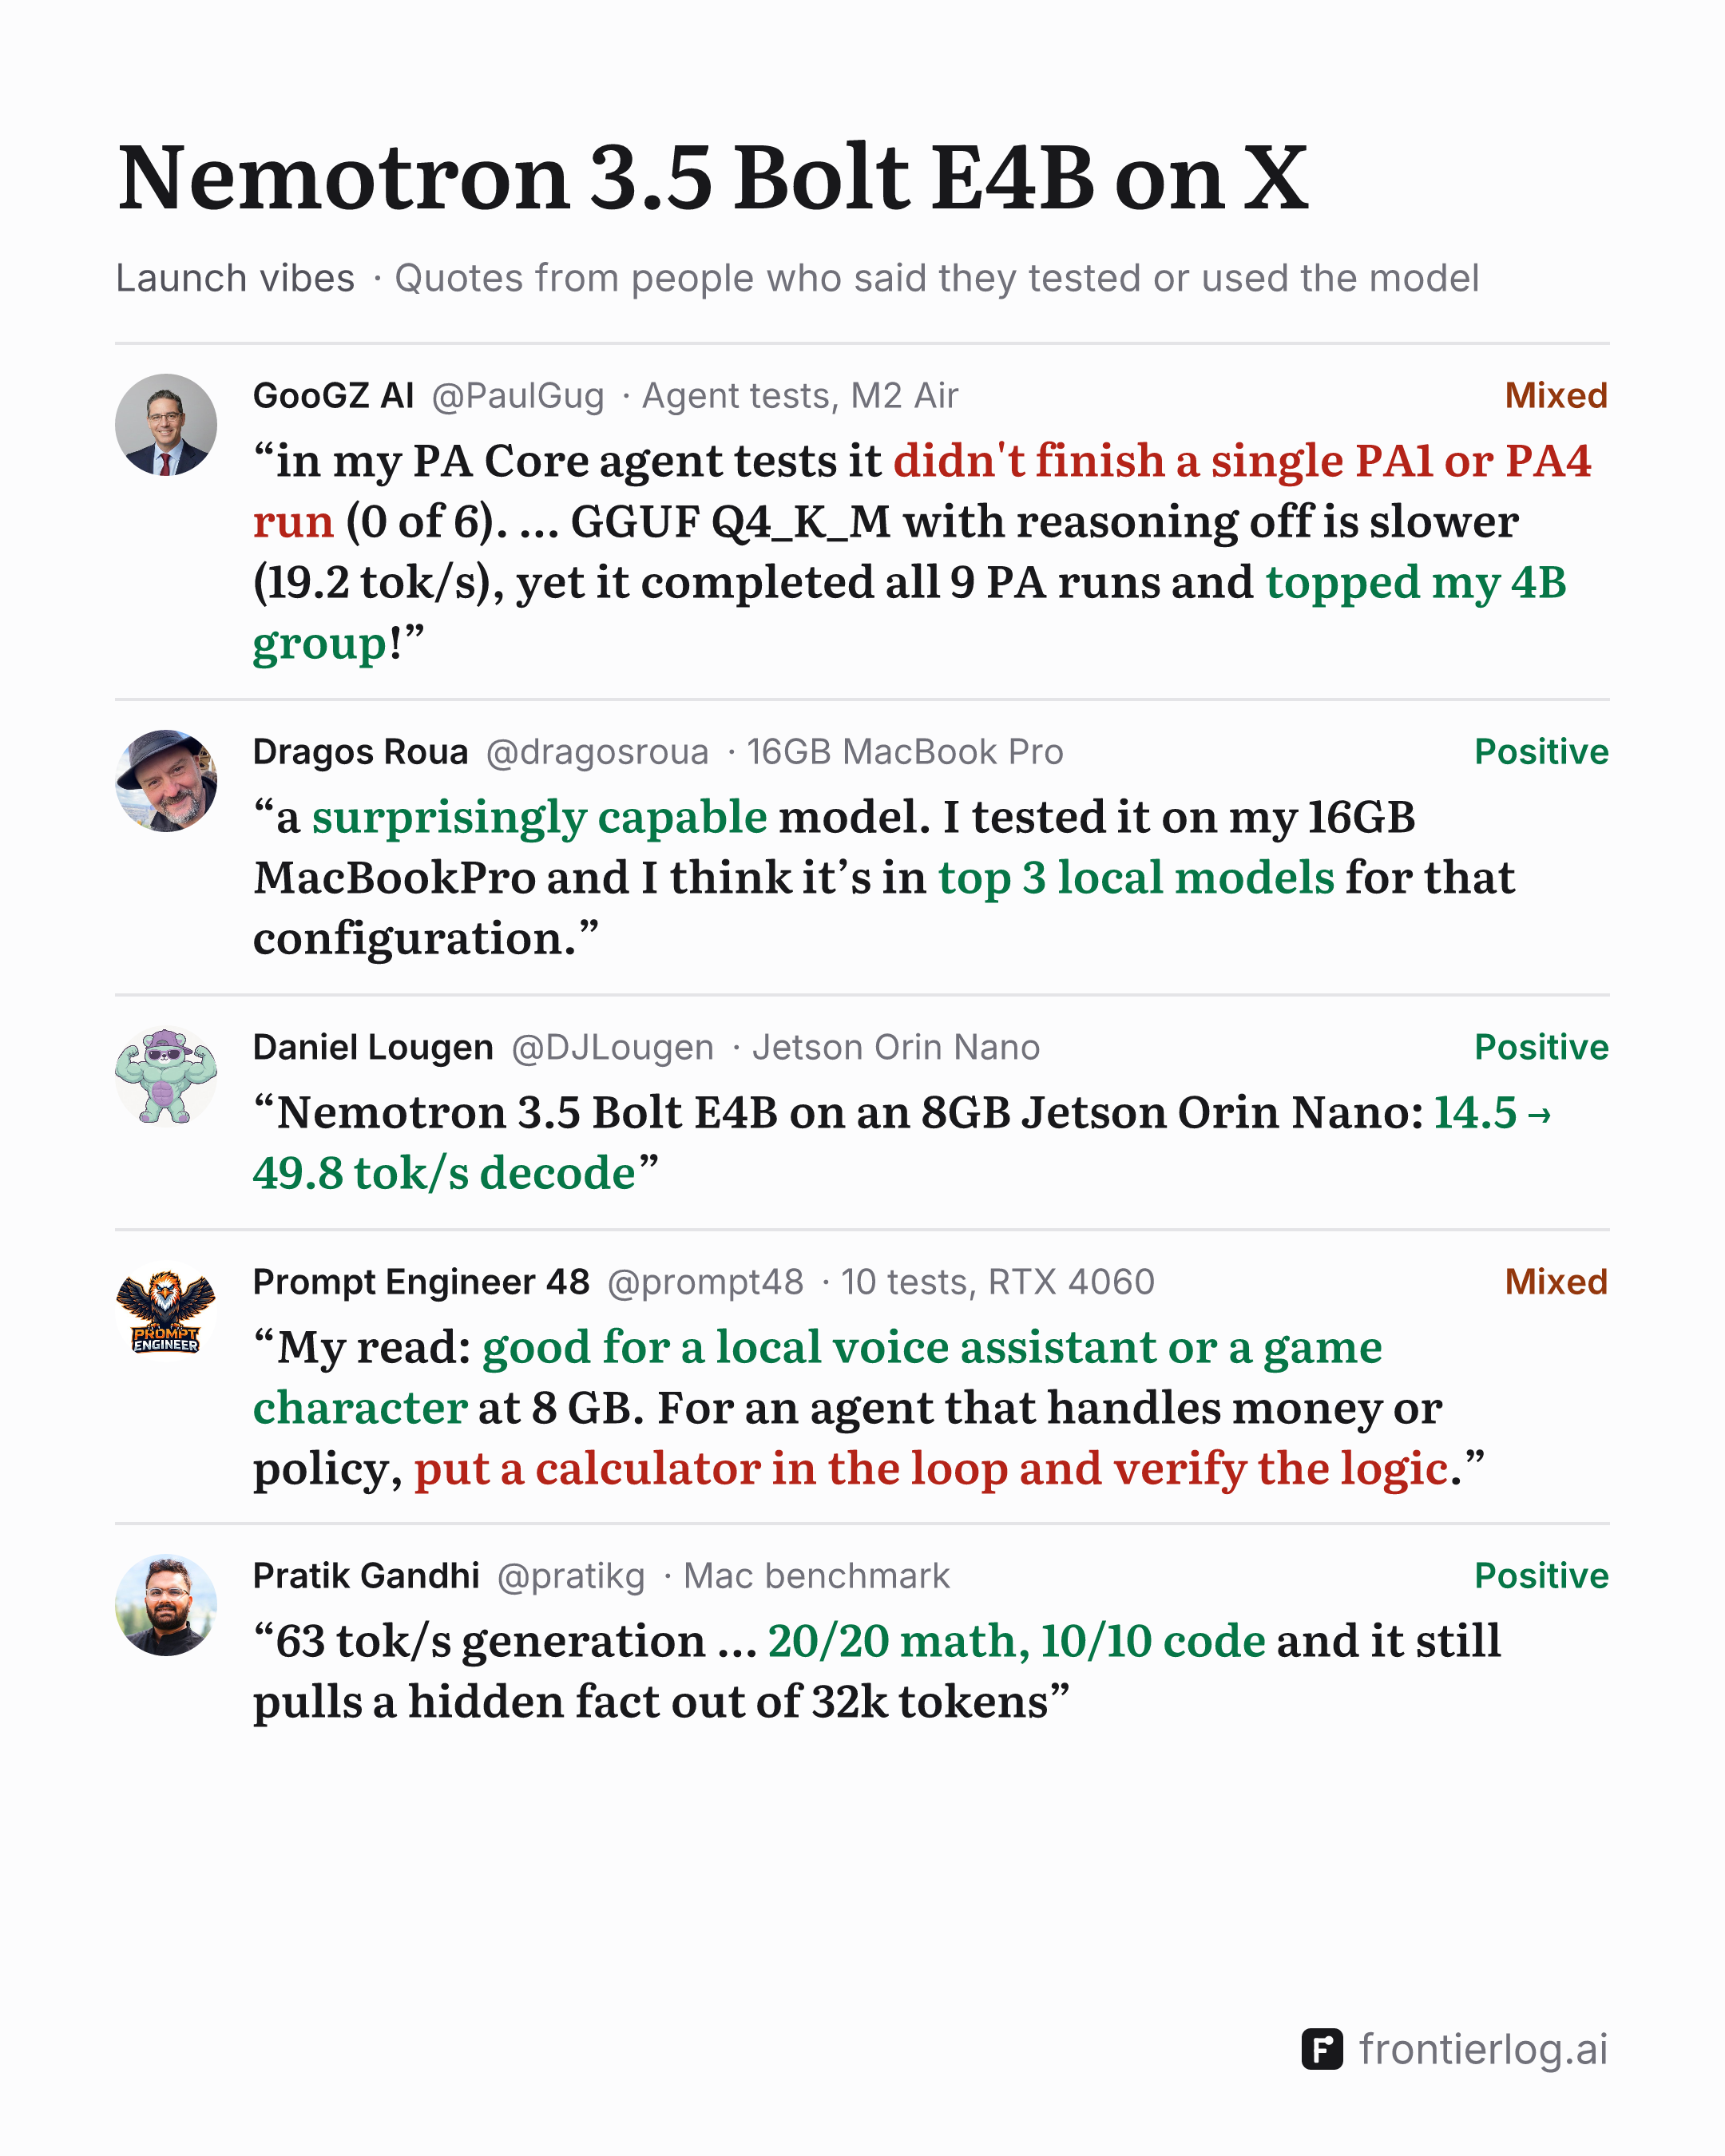
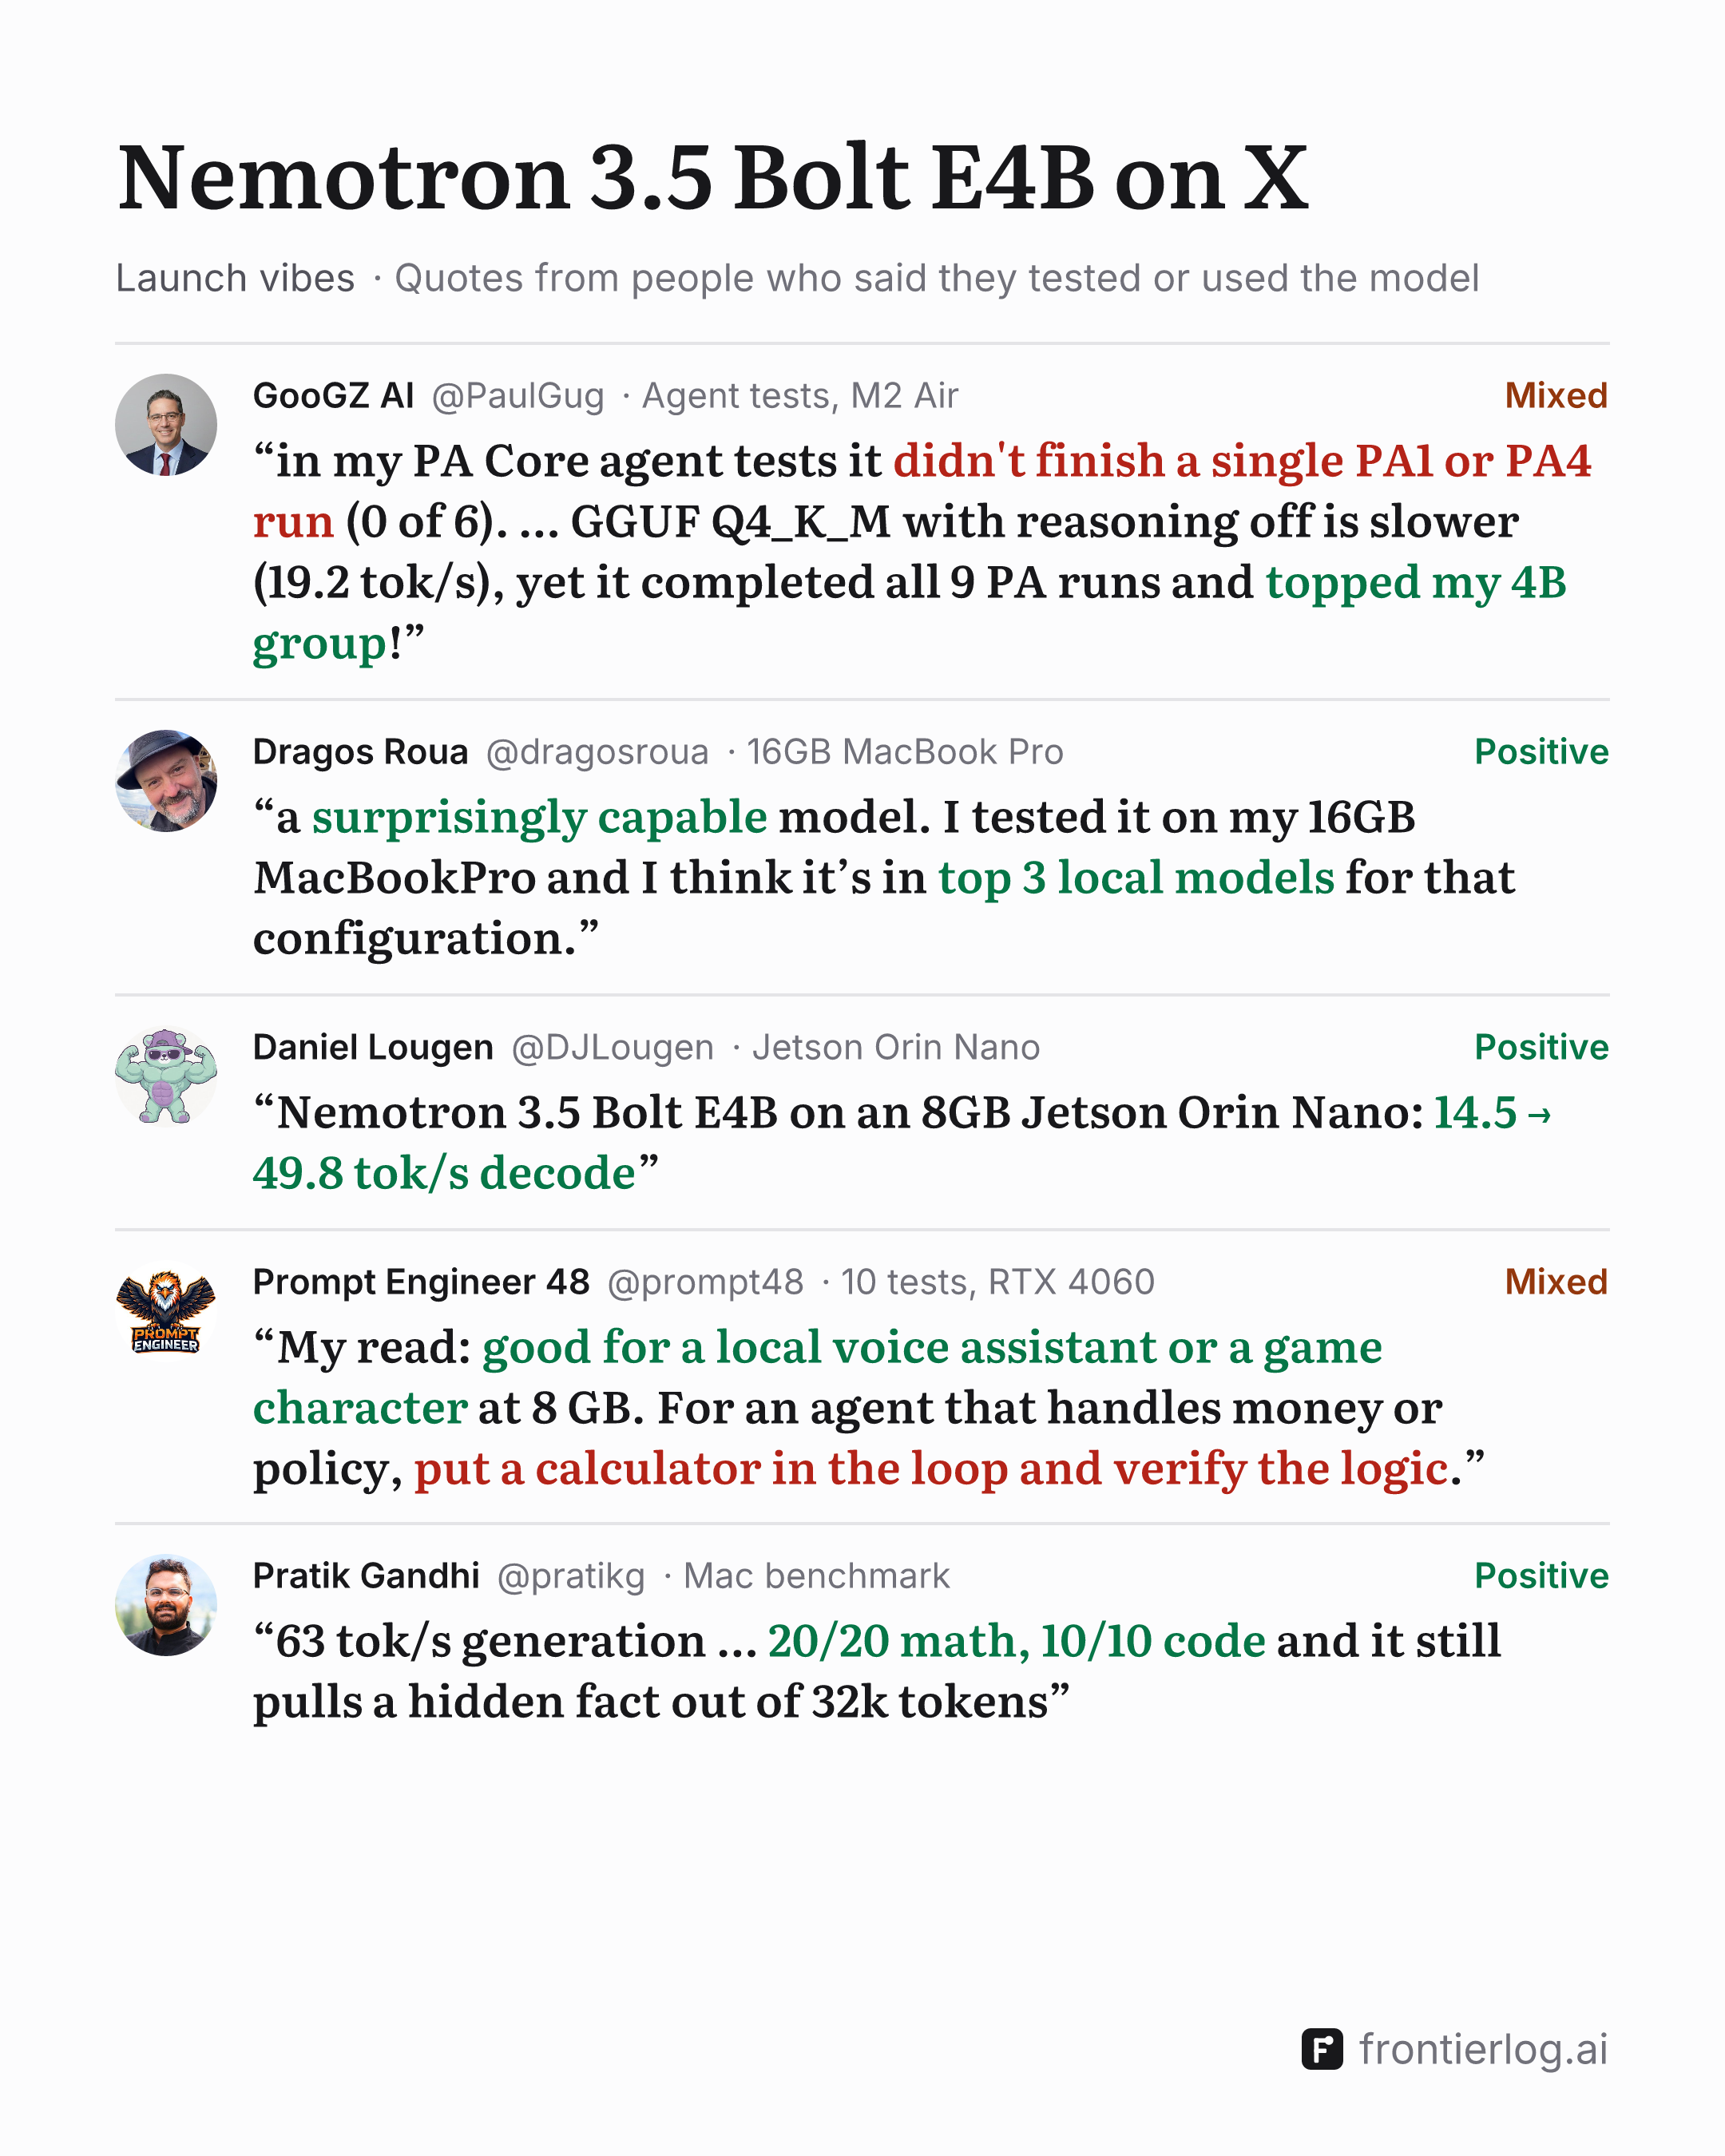
Nemotron 3.5 Bolt E4B on X, launch vibes: quotes from X posts, each with its author and sentiment. GooGZ AI (@PaulGug), mixed: “in my PA Core agent tests it didn't finish a single PA1 or PA4 run (0 of 6). … GGUF Q4_K_M with reasoning off is slower (19.2 tok/s), yet it completed all 9 PA runs and topped my 4B group!” Dragos Roua (@dragosroua), positive: “a surprisingly capable model. I tested it on my 16GB MacBookPro and I think it’s in top 3 local models for that configuration.” Daniel Lougen (@DJLougen), positive: “Nemotron 3.5 Bolt E4B on an 8GB Jetson Orin Nano: 14.5 → 49.8 tok/s decode” Prompt Engineer 48 (@prompt48), mixed: “My read: good for a local voice assistant or a game character at 8 GB. For an agent that handles money or policy, put a calculator in the loop and verify the logic.” Pratik Gandhi (@pratikg), positive: “63 tok/s generation … 20/20 math, 10/10 code and it still pulls a hidden fact out of 32k tokens”
Download
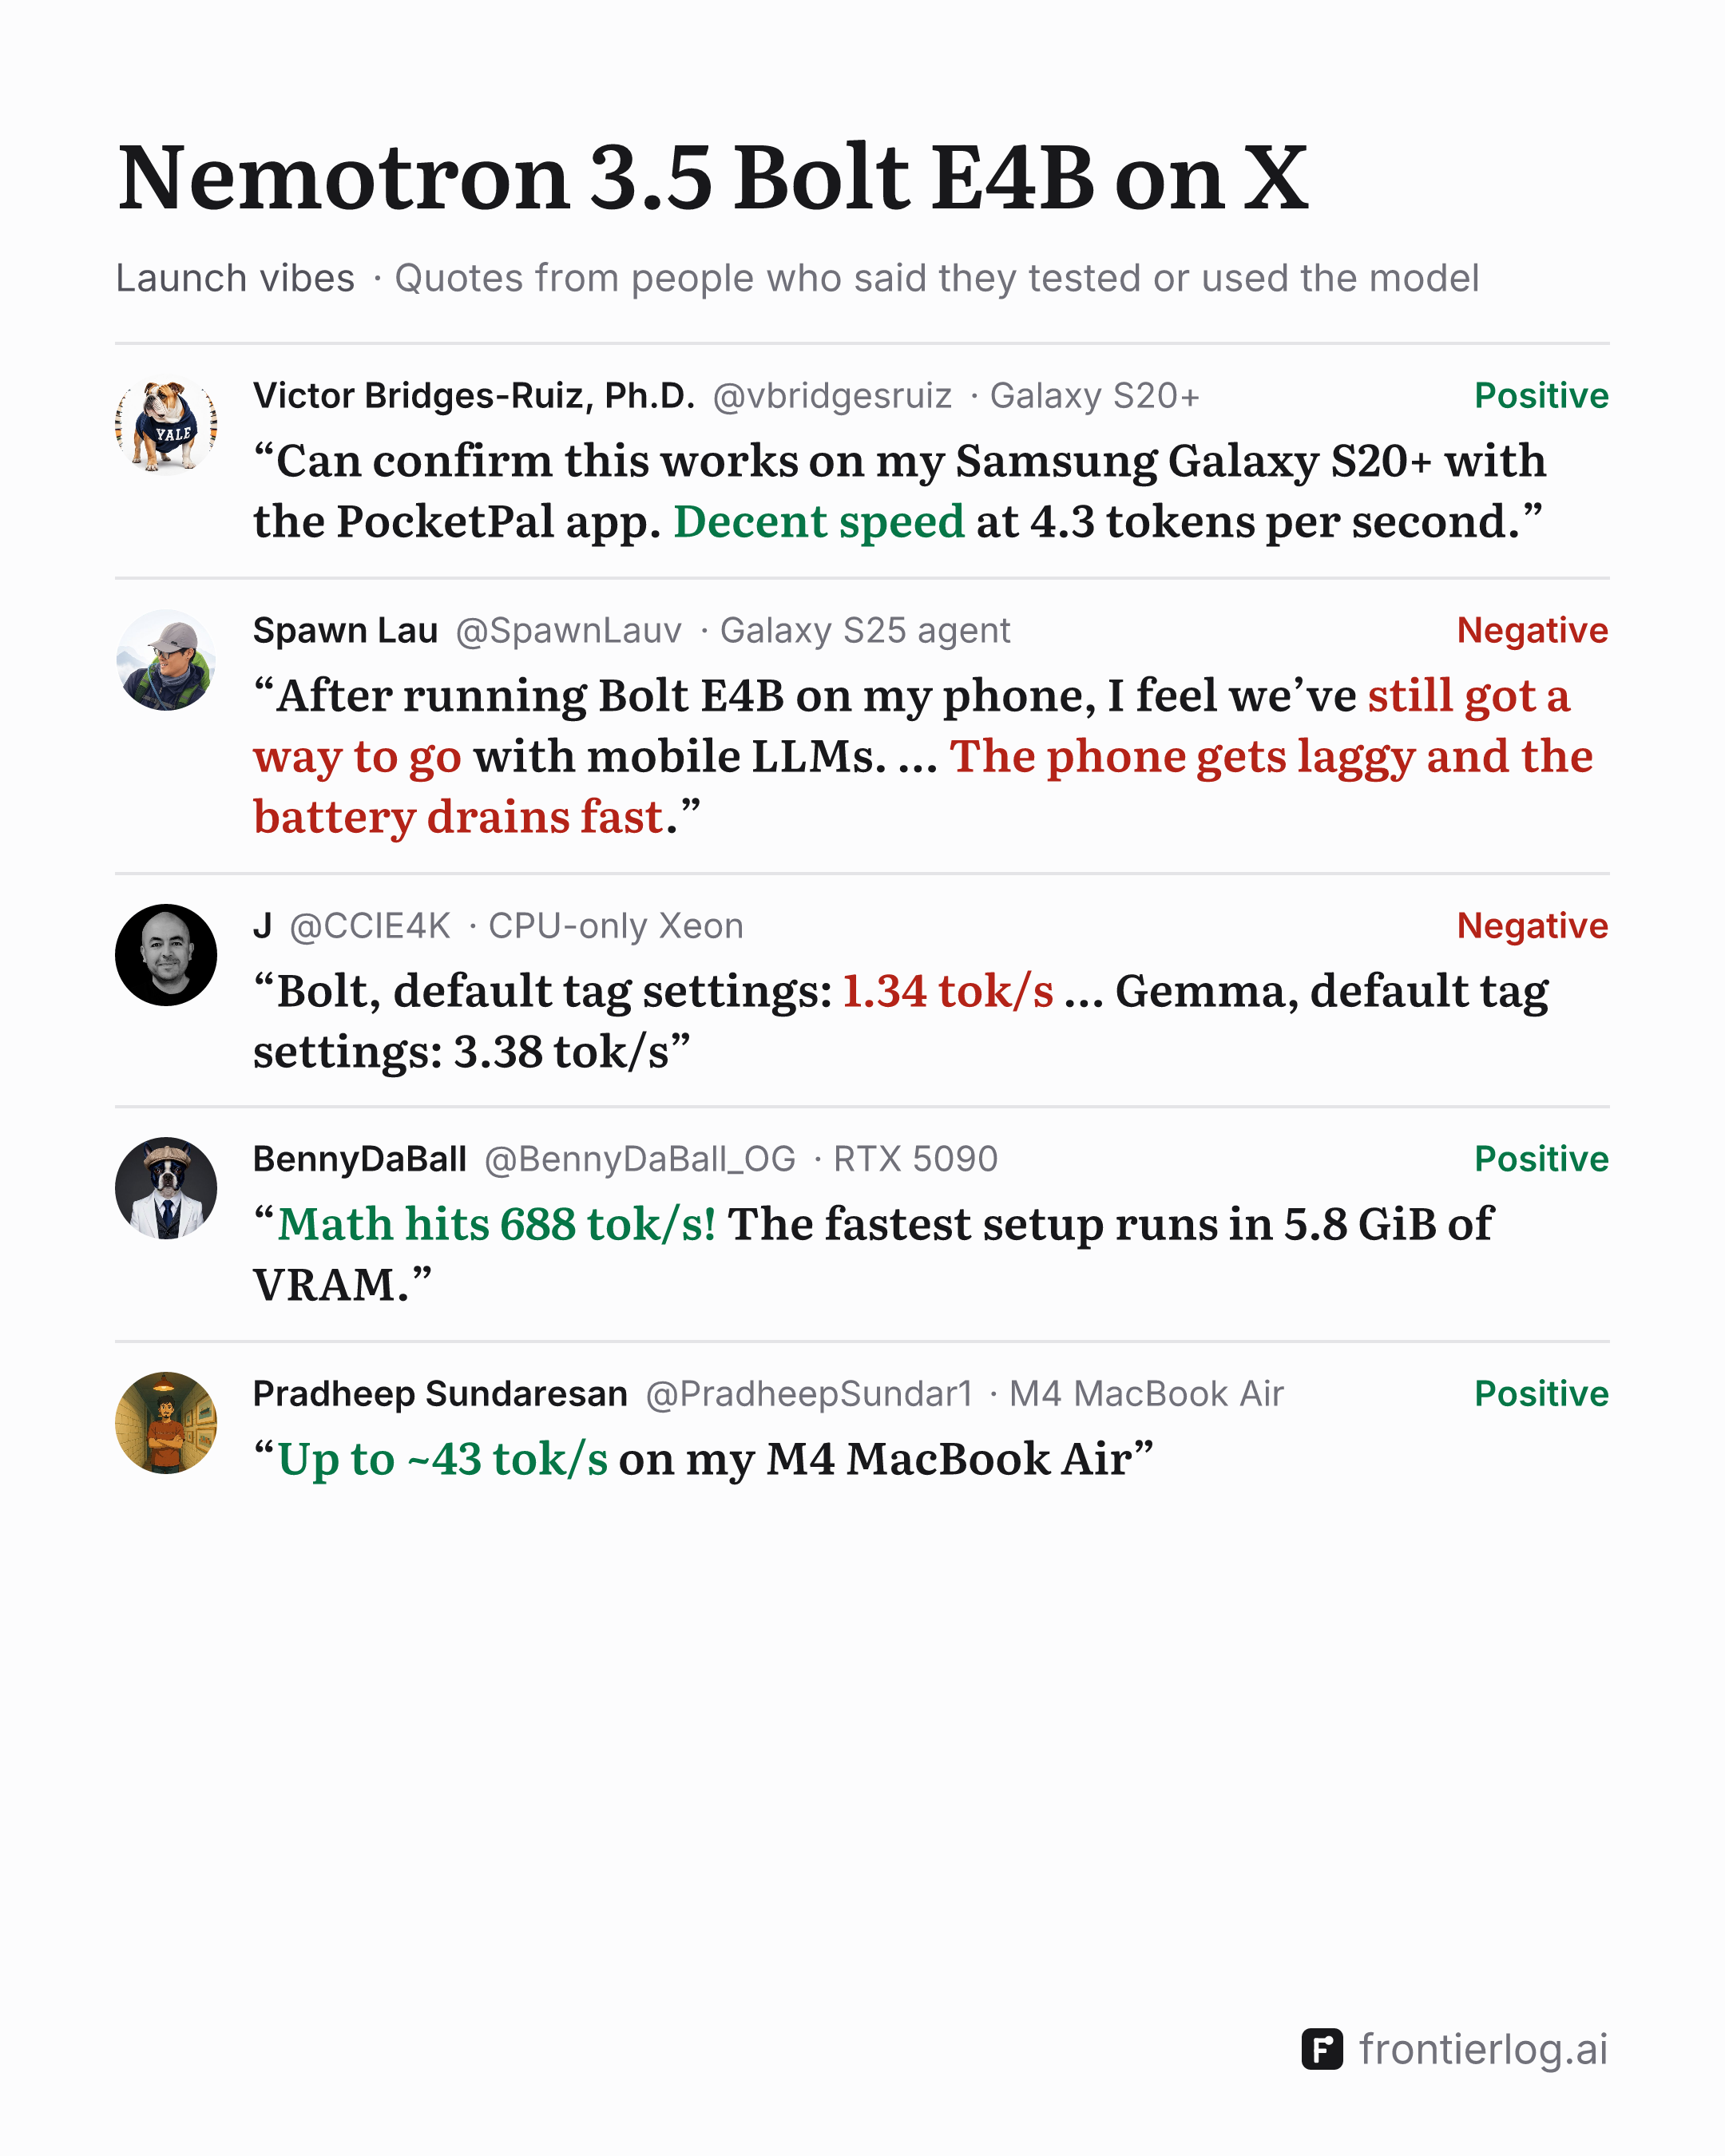
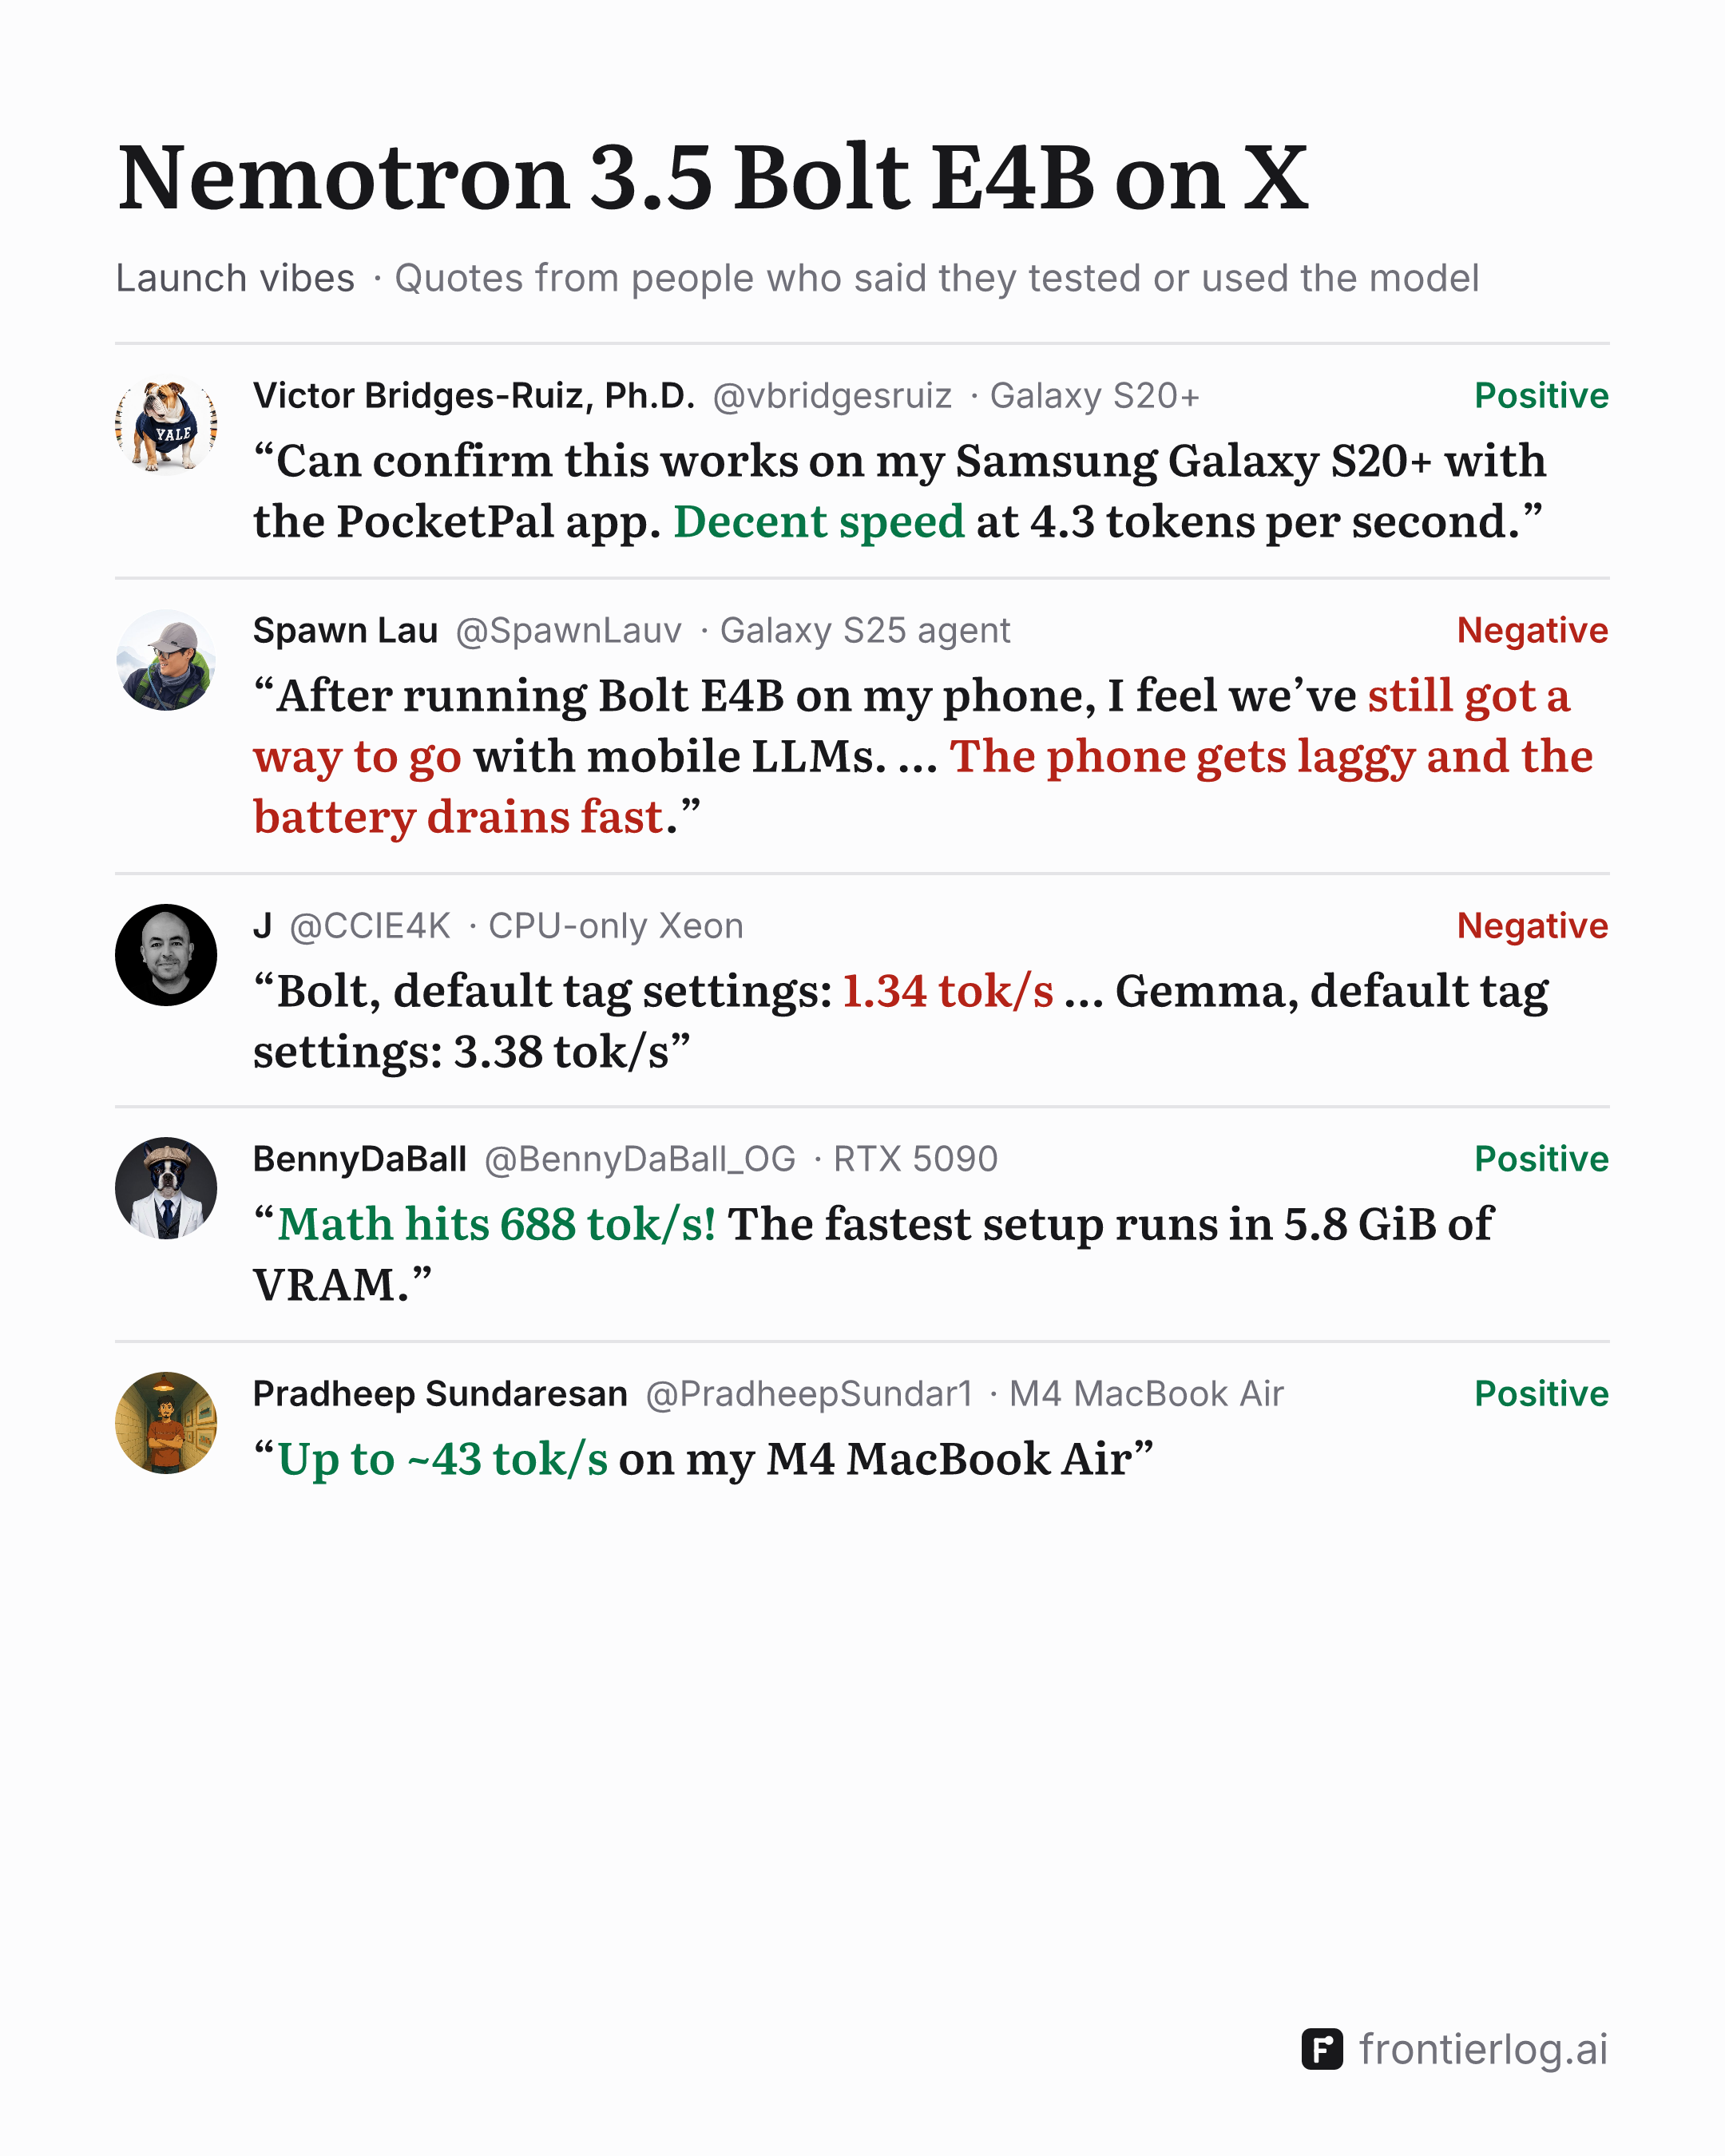
Nemotron 3.5 Bolt E4B on X, launch vibes: quotes from X posts, each with its author and sentiment. Victor Bridges-Ruiz, Ph.D. (@vbridgesruiz), positive: “Can confirm this works on my Samsung Galaxy S20+ with the PocketPal app. Decent speed at 4.3 tokens per second.” Spawn Lau (@SpawnLauv), negative: “After running Bolt E4B on my phone, I feel we’ve still got a way to go with mobile LLMs. … The phone gets laggy and the battery drains fast.” J (@CCIE4K), negative: “Bolt, default tag settings: 1.34 tok/s … Gemma, default tag settings: 3.38 tok/s” BennyDaBall (@BennyDaBall_OG), positive: “Math hits 688 tok/s! The fastest setup runs in 5.8 GiB of VRAM.” Pradheep Sundaresan (@PradheepSundar1), positive: “Up to ~43 tok/s on my M4 MacBook Air”
Download
  1. Victor Bridges-Ruiz, Ph.D. @vbridgesruizPositive

    “Can confirm this works on my Samsung Galaxy S20+ with the PocketPal app. Decent speed at 4.3 tokens per second.”
    Galaxy S20+ ·

  2. GooGZ AI @PaulGugMixed

    “in my PA Core agent tests it didn't finish a single PA1 or PA4 run (0 of 6). … GGUF Q4_K_M with reasoning off is slower (19.2 tok/s), yet it completed all 9 PA runs and topped my 4B group!”
    Agent tests, M2 Air ·

  3. Spawn Lau @SpawnLauvNegative

    “After running Bolt E4B on my phone, I feel we’ve still got a way to go with mobile LLMs. … The phone gets laggy and the battery drains fast.”
    Galaxy S25 agent ·

  4. J @CCIE4KNegative

    “Bolt, default tag settings: 1.34 tok/s … Gemma, default tag settings: 3.38 tok/s”
    CPU-only Xeon ·

  5. Dragos Roua @dragosrouaPositive

    “a surprisingly capable model. I tested it on my 16GB MacBookPro and I think it’s in top 3 local models for that configuration.”
    16GB MacBook Pro ·

  6. Daniel Lougen @DJLougenPositive

    “Nemotron 3.5 Bolt E4B on an 8GB Jetson Orin Nano: 14.5 → 49.8 tok/s decode”
    Jetson Orin Nano ·

  7. BennyDaBall @BennyDaBall_OGPositive

    “Math hits 688 tok/s! The fastest setup runs in 5.8 GiB of VRAM.”
    RTX 5090 ·

  8. Prompt Engineer 48 @prompt48Mixed

    “My read: good for a local voice assistant or a game character at 8 GB. For an agent that handles money or policy, put a calculator in the loop and verify the logic.”
    10 tests, RTX 4060 ·

  9. Pradheep Sundaresan @PradheepSundar1Positive

    “Up to ~43 tok/s on my M4 MacBook Air”

    M4 MacBook Air ·

  10. Pratik Gandhi @pratikgPositive

    “63 tok/s generation … 20/20 math, 10/10 code and it still pulls a hidden fact out of 32k tokens”

    Mac benchmark ·

This page quotes only posts from people on X who said they had tested or used Nemotron 3.5 Bolt E4B.